A customer needs an answer. An invoice needs checking. Your team wants to try a new tool. Start with a familiar problem, see what is happening, and choose what you would do. No technical background needed.
Meet the problem
See what is happening
Make a choice
Find out why
Try a small change
All decisions are free without an account or API key. Drafts stay on this device only, not in account sync. Follow-up lessons retain their existing sign-in and plan requirements.
These are made-up (synthetic) stories with feedback written in advance, not live AI results or real customer outcomes. They help you practise, but do not certify your skills.
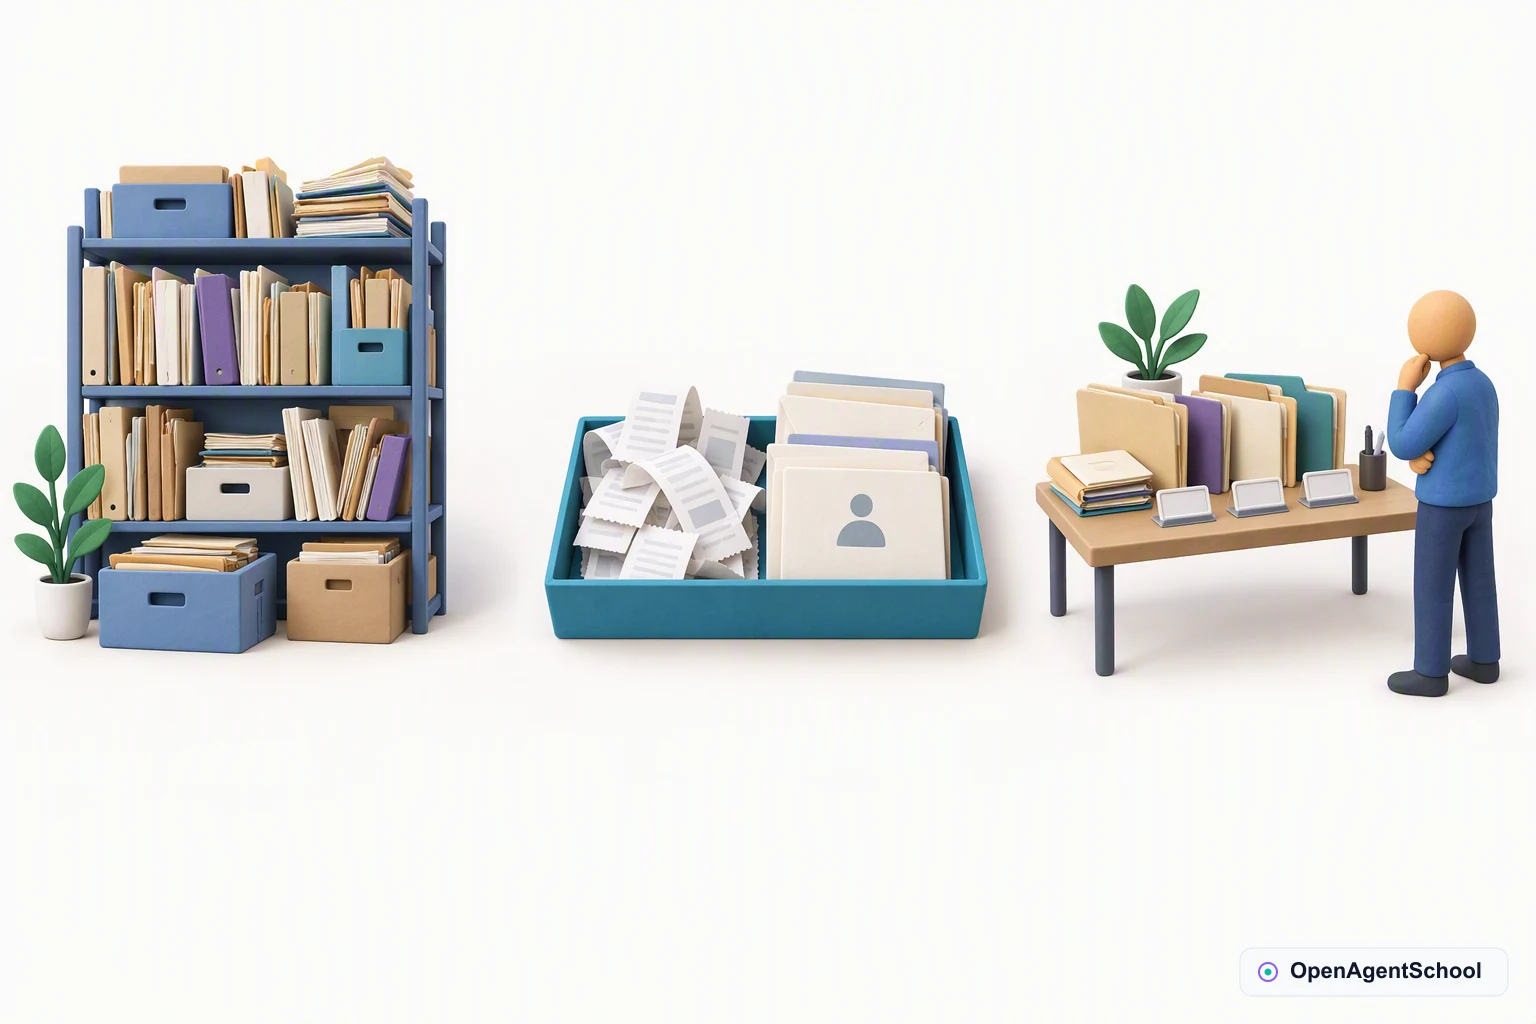
A customer brings back shoes bought on sale last week. You work at the shop and use an AI helper to draft replies. The shop has different return rules for different items, and those rules sometimes change.
The problem: Give this customer the rule that applies to their shoes, rather than a confident answer about how returns usually work.
Picture the situation: Read from the purchase, through the possible shop rules, to the customer waiting to learn which rule applies to these shoes.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Last week: sale shoes
The receipt shows the item, shop and purchase date.
Several return rules
The shop keeps separate rules for different items and dates.
Can I return them?
A customer is waiting for your reply at the counter.
What would you do?
What would you ask the AI helper to do first?
Draft an answer from the usual 30-day ruleWhy this choice?
That rule sounds familiar, but this shop may treat sale shoes differently. A friendly answer still needs the right shop rule behind it.
Find the current shop rule for these shoesWhy this choice?
The item and purchase date help find the right rule. Ask for the source beside the draft so you can check it before replying. If no clear rule covers the shoes, ask the shop manager.
Reuse last week's answer to another customerWhy this choice?
An earlier reply can help with wording, but the other customer may have bought a different item. Check today's applicable rule before reusing its answer.
What to take away
Start with the shop's applicable rule, then write the reply. Sounding certain is not the same as knowing what this customer is entitled to.
What if something changes?
The shop manager posts a short, dated notice covering this sale. It names these shoes and says they can be returned within 14 days. The AI search still shows the old rule. The customer has their receipt from seven days ago.
How would you answer this customer now?
Show the new notice and explain the 14-day ruleWhy this choice?
The manager's notice covers these shoes and this purchase date. You can answer directly from it; there is no need to make the AI rewrite one clear sentence.
Use the AI search result because it checks more documentsWhy this choice?
More documents do not help if the answer misses today's notice. The old search result is not the current rule for this sale.
Ask the customer to wait until AI search catches upWhy this choice?
Waiting would make sense if the rule were unclear. Here, the manager has already supplied a clear answer for this purchase, so waiting adds work without resolving anything.
What to take away
When one trusted, up-to-date notice answers the question, use it directly. An AI helper is useful only if it makes the job easier.
The idea behind this story
Find the rule that applies, not just an answer that sounds right.
Where would you look if a confident answer disagreed with the shop's latest notice?
The technical connection: Grounding and retrieval
Grounding means tying an answer to a source you can check. Retrieval finds relevant source material for the AI. If that search is out of date, a current source may be more useful on its own.
Advanced: Answer the policy, not a plausible policy
Choose how a support assistant finds current evidence, then respond when the evidence service cannot keep up.
Customer support · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A service team wants draft answers about returns across product lines; staff currently search policy documents and must verify the policy before replying.
Your initial decision
How should the first assistant help staff answer a policy question?
The illustrative corpus contains 600 approved documents with product, region, effective-date and access metadata.
Questions usually concern one product and region; exact product codes and natural-language descriptions both matter.
Policy updates arrive daily; the assistant may draft replies but cannot approve exceptions or issue refunds.
Unsupported or conflicting evidence must produce a handoff, not an invented policy.
Compare the alternatives
Offer a product-and-region source menu
A product-and-region lookup is easy to audit but leaves staff to read and reconcile long documents.
Draft from filtered retrieved passages
Combine keyword and semantic retrieval with access and effective-date filters; ranking needs tuning and freshness monitoring.
Put complete permitted policy documents in context
Full-document prompting preserves surrounding exceptions and avoids chunk tuning, but broad product queries create large contexts that must be refreshed and access-filtered.
Mechanism, trade-offs, and evidence
Start with the task: staff need the currently applicable rule, not the most fluent paragraph; compare against their existing lookup workflow.
Lexical search preserves exact codes while semantic search helps paraphrases, but neither establishes access or policy validity without metadata filters.
Evaluate retrieval misses separately from unsupported generation and include conflicts and unanswerable questions in a held-out task set.
A graph is not justified by mostly local policy questions; introduce relationship retrieval only if a distinct multi-document failure appears.
Reconsider after a change
During a policy migration, the index is stale and new effective-date mappings are not yet validated; the pilot is temporarily narrowed to a signed emergency bulletin.
What should staff use until the migration is verified?
In this synthetic phase, only 12 short bulletin entries are in scope and staff can select the relevant entry directly.
The index has a 48-hour update lag, exceeding the illustrative same-day freshness requirement.
The signed bulletin is the temporary authority; wider policy questions require a human policy owner.
The migration needs access and effective-date regression checks before normal retrieval resumes.
Compare the alternatives
Restore the filtered retrieval pipeline
Restoring the filtered pipeline can recover broad coverage but requires verified mappings and freshness monitoring before release.
Generate answers from the complete signed bulletin
Passing the bulletin directly avoids the stale index and preserves its full context, but generated synthesis adds verification work to a small set of directly selectable entries.
Return the selected bulletin entry directly
A deterministic selector returns the signed excerpt and source link immediately; staff must select the region and confirm coverage, while cross-policy questions still require a handoff.
Mechanism, trade-offs, and evidence
The original architecture was conditional on fresh, valid evidence; that assumption has changed even though the model has not.
A narrower deterministic source now meets the immediate need with less uncertainty, so reducing complexity is a justified adaptation.
Record deferred questions and migration failures to guide restoration, rather than silently treating reduced coverage as full service.
After validation, compare the restored pipeline with direct lookup again; the former recommendation is not a permanent commitment.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
You approve a customer's refund and press Submit in the payment screen. The screen freezes, then shows Pending. The customer asks whether to wait. Your AI helper can read the refund record, but it cannot issue refunds.
The problem: Find out what happened to the approved refund without accidentally paying it twice or telling the customer it failed when it did not.
Picture the situation: Follow the submitted request to the stalled screen and waiting customer; the picture leaves open whether the money has moved.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
One approved refund
You submitted a refund for the customer's returned order.
Screen says Pending
The payment screen froze after you pressed Submit.
The customer is waiting
They want to know whether the money is on its way.
What would you do?
What should happen before anyone tries another refund?
Press Submit again to get a clear answerWhy this choice?
The first refund may already be moving even though the screen froze. Another submission could pay twice. A frozen screen is a reason to check the existing refund, not start a new one.
Tell the customer the refund failedWhy this choice?
Pending does not mean failed. Explain that the outcome is still being checked, so the customer is not given a false answer or encouraged to request a second refund.
Check the existing refund in the payment recordWhy this choice?
Match the order, amount and refund reference. If the record remains unclear, ask the payments team to trace that refund and keep the customer updated. Do not submit another refund while its outcome is unknown.
What to take away
A missing confirmation is not a failed payment. Check the refund already submitted before deciding what to tell the customer.
What if something changes?
The payment record now confirms that the original refund succeeded for the correct order and amount. The customer has not received an email and asks you to send the refund again. You have the receipt and the payment service's expected bank arrival window.
What does the customer need now?
Keep waiting without replying until an email arrivesWhy this choice?
You now know the refund succeeded, so you can help without moving more money. Waiting silently leaves the customer unsure about an outcome you can explain.
Send the receipt through the shop's approved customer channelWhy this choice?
Confirm the original refund and share its reference and expected bank arrival window with this customer. Missing email does not call for another refund. If the money does not arrive within that window, ask the payments team to trace it.
Create another refund so a fresh email gets sentWhy this choice?
The original refund succeeded. Creating another would move money twice to solve an email problem. Use the existing receipt instead.
What to take away
Once the payment is confirmed, solve the communication problem: send the receipt and explain the next step. Do not repeat a money transfer to replace a missing message.
The idea behind this story
Check what happened to the money, not just what happened to the screen.
What would you want to see before telling someone their refund had failed?
The technical connection: Transaction state
Transaction state is the recorded status of a payment. A screen can lose its reply while the payment succeeds. Software needs a reliable way to check the original payment; an AI guess cannot replace that record.
Advanced: A refund timeout is not a failed refund
Separate conversation, authorization and transaction state before deciding whether an agent may execute a refund.
Transactions and customer operations · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A retailer wants to reduce refund handling effort while preserving customer consent, refund policy and an auditable payment ledger.
Your initial decision
What authority should the pilot agent receive?
Staff must approve each refund under the current policy; conversational requests do not bypass that requirement.
The legacy refund adapter has no stable operation identifier or reliable status reconciliation.
A payment can complete while its response is lost; duplicate refunds create financial and customer harm.
The agent may read only records for the authenticated customer and must not retain payment credentials in context.
Compare the alternatives
Build a guarded transaction gateway before any write pilot
Durable operation IDs, approval binding and reconciliation could support later execution, but implementation and failure testing delay that release.
Automate console entry with staff confirmation
An isolated UI agent can enter an approved refund and stop after submission, but screen changes and ambiguous receipts complicate verification and recovery.
Draft proposals for staff console execution
The model gathers eligibility evidence while staff use the established payment console; manual re-entry remains a cost and a potential error, so staff compare the proposal with the confirmation.
Mechanism, trade-offs, and evidence
Separate interpreting the request from authorizing the amount and executing the payment; these are different trust boundaries.
An MCP tool schema can standardize access but does not fix transaction semantics or grant refund authority.
The immediate safe baseline is a proposal plus established staff execution, while engineering repairs the write path.
Version rollback cannot undo money already moved; recovery needs reconciliation and an authorized financial process.
Reconsider after a change
The backend now has durable operation records and a tested reconciliation path; a narrowly scoped execution pilot is proposed, still requiring staff approval.
Does the new evidence justify any agent-initiated execution?
In an illustrative independent suite of 240 sandbox transactions, duplicate delivery, concurrent requests and lost responses produced no duplicate ledger effects; this is finite test evidence, not a guarantee.
Approval is server-bound to the customer, order, amount and expiry, and every write rechecks current policy.
The synthetic pilot permits refunds up to $25 after staff approval, with a daily cap of 10 and an immediate disable switch.
Unknown outcomes enter reconciliation without a new operation ID; exceptions and expired approvals return to staff.
Compare the alternatives
Canary the guarded refund API
The agent submits an approved proposal through scoped credentials and durable idempotency controls, reducing console re-entry while adding operational monitoring.
Keep staff execution until operational coverage is available
Manual execution preserves the established recovery workflow but forgoes the demonstrated reduction in re-entry work.
Keep the supervised console automation path
Reusing a UI adapter avoids migrating its callers and retains staff confirmation, but duplicates integration work now that the API exposes authoritative operation status.
Mechanism, trade-offs, and evidence
The recommendation changes because the missing engineering controls now exist and have task-specific evidence, not because a model became newer.
Check provider-specific idempotency retention and error semantics rather than assuming the same key prevents duplicates forever.
A scoped canary limits exposure while measuring correct refunds, review burden and unresolved outcomes against staff execution.
If a refund is wrong, disabling the agent prevents future actions but does not reverse the payment; use the authorized remediation procedure.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
On your team's website, the Save button does not keep a person's display name. An AI coding helper offers a fix and says its checks pass. The same website also holds passwords and payment details.
The problem: Get Save working without accidentally changing who can sign in or see someone else's account.
Picture the situation: The loose name strip introduces the problem, the replacement tile shows a proposed change, and the maintainer represents the review still ahead.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Name did not save
A person changes their display name, but the old name returns.
An AI offers a fix
The helper has changed some files and reports passing checks.
Someone must approve it
Your team has not yet reviewed the changes.
What would you do?
What would you ask for before putting the fix live?
Have the maintainer review and try the small fixWhy this choice?
Show that the Save problem happens before the change and is gone afterward. The maintainer should inspect the changed files and check that one person still cannot edit another's account. The AI should work on test accounts without live passwords or payment details.
Publish it because the AI's checks passedWhy this choice?
Those checks are useful, but they may miss the account rule the team cares about. A maintainer still needs to review what changed and approve the release.
Ask the AI to tidy all account code at the same timeWhy this choice?
A cleanup could be useful later, but it makes this fix harder to review. First find out whether the small Save change works without changing account access.
What to take away
Ask for a small change you can check against the original problem. Passing checks help a reviewer; they do not replace the person responsible for the release.
What if something changes?
The maintainer finds that two family members can share a display name. The proposed fix would combine their stored accounts. The helper offers a newer AI model with a higher coding score, but the team has not tried this change on separate family accounts.
What needs to change about the plan?
Use the newer AI and release after its checks passWhy this choice?
A higher coding score does not tell you whether these family accounts stay separate. The team needs checks for this website and a reviewed way to recover changed account data.
Keep reviewing only whether the Save button worksWhy this choice?
The job now affects stored accounts, not just a button. A successful name change could still merge two people's data, and reverting the button code would not necessarily separate it again.
Pause release and involve the account maintainerWhy this choice?
The account maintainer should review how existing data changes, test separate family accounts and check that access stays separate. Rehearse recovery on test data before approving release. Keep the work focused; a newer model does not make this a smaller change.
What to take away
When a small fix turns into a change to people's stored accounts, widen the review to match the risk. A better coding score does not shrink that responsibility.
The idea behind this story
Check what the change does to people, not just whether the button works.
If Save worked but two people's accounts were mixed together, which check would have been missing?
The technical connection: Change review and regression tests
Change review means a responsible person checks the actual edits. Regression tests check that a fix does not break behavior that already worked. Changes to stored data also need a tested recovery plan.
Advanced: Passing tests are evidence, not merge authority
Review an agent-authored repository change and decide what a better coding benchmark should actually change.
Software engineering · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A team asks a coding agent to fix an account-settings defect in a repository that also contains billing and authentication code.
Your initial decision
Which implementation and review path fits this bug?
The requirement is narrow: changing a display preference must not affect account permissions.
Repository text and downloaded dependencies are untrusted inputs; production secrets must not enter the execution environment.
A maintainer owns merge approval and can review a focused diff, but not an unrelated repository-wide refactor.
Tests generated by the author are useful but cannot alone establish the intended access behavior.
Compare the alternatives
Review a focused agent-authored patch
The agent reproduces the bug and runs permitted tests while a maintainer checks requirements, access boundaries and the final diff, adding review effort.
Have a maintainer implement the fix directly
A small human patch avoids agent setup and trust overhead but uses maintainer implementation time.
Refactor the settings layer before fixing the defect
A reviewed refactor could remove duplicated state handling and make later fixes easier, but expands the diff and regression surface beyond the requested behavior.
Mechanism, trade-offs, and evidence
State the invariant before implementation: preferences must not alter permissions; derive an independent negative test from it.
Keep the workspace and credentials narrow because repository instructions can be malicious or simply inappropriate for the task.
Review the diff as executable behavior, including dependency and configuration changes, rather than relying on the agent summary.
Save a reproducible test result and a reversible patch; a tool-use transcript alone does not show that the user-visible defect is fixed.
Reconsider after a change
A new model advertises a higher coding score, while investigation reveals that the fix also requires an authentication migration.
Should the team relax review for the new model?
The advertised benchmark improvement is not a result on this repository and provides no local migration evidence.
In this illustrative migration, 3 permission states must preserve access correctly, including suspended accounts.
A rollback must account for stored data changes; reverting code alone may not restore the previous state.
The maintainer can stage the migration and arrange a security-owner review before release.
Compare the alternatives
Combine migration with a reviewed settings refactor
The stronger coding model could consolidate state and permission handling together, but combining structural and data changes makes regressions harder to isolate and reverse.
Keep the patch and migration narrowly reviewed
Split schema and behavior changes, test all permission states and rehearse rollback with the responsible owners, accepting a slower release.
Have the maintainer implement the migration directly
A maintainer who knows the data invariants can avoid reviewing unfamiliar generated migration logic, but implementation still competes with their limited review and operations time.
Mechanism, trade-offs, and evidence
Reconsideration does not require changing the answer; identify which assumptions changed and whether they weaken or strengthen the original boundary.
Use the new model as a candidate implementation tool while holding acceptance tests and ownership constant.
Test migration and rollback on representative synthetic account states, including partial failure, before exposing real accounts.
The outcome sought is correct user access with manageable recovery, not the fastest generated patch.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
You help run a small online shop. Customers report that checkout will not finish. An AI helper says the website may need a restart. The person responsible for the website has been called, but has not yet seen what is happening.
The problem: Help the website owner understand the checkout failure quickly without making a guess that could interrupt orders still being processed.
Picture the situation: The stalled checkout and customer messages describe the problem; the separate restart suggestion has not yet been checked or carried out.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Checkout will not finish
Customers are stuck at the final step of placing an order.
Messages are coming in
Several shoppers describe the same problem.
Maybe restart the website?
The AI offers a possible cause before the owner has checked.
What would you do?
What is the most useful job for the AI right now?
Restart the live website to see whether that helpsWhy this choice?
A restart might help some problems, but it can also interrupt orders. A possible cause is not permission to change the live website. Leave that decision with the website owner.
Gather the error times and recent website changesWhy this choice?
Give the owner a short account of what failed, when it started and what changed recently, using the shop's approved checks. Leave out customer payment details. If a check is unavailable, say so rather than filling the gap with a guess.
Hold the alert until the AI is sure of the causeWhy this choice?
Customers already cannot place orders. Keep the owner informed while the cause is being checked; waiting for AI certainty could delay help without making the diagnosis right.
What to take away
Help the responsible person see what is happening. Keep the alert moving, and keep live website changes separate from the AI's suggestions.
What if something changes?
The website owner checks the failed orders and finds a new checkout setting is responsible. They have a tested way to restore the previous setting and approve doing it now. The AI is still suggesting a full restart.
What should the team do with the AI's suggestion now?
Have the owner restore the checked setting and watch checkoutWhy this choice?
The owner has checked the cause and approved a known repair. They can make the change while the AI helps watch whether checkout recovers. Record what happened and keep watching for failed orders; the repair still needs confirmation.
Delay the repair until the AI agrees with the ownerWhy this choice?
The owner has information the AI suggestion does not reflect. Waiting for agreement adds delay; use the checked repair and confirm whether customers can place orders again.
Let the AI restart everything as wellWhy this choice?
Approval to restore one setting is not approval for a full restart. Adding another change can interrupt orders and make it harder to tell which action helped.
What to take away
Move from gathering facts to the owner's approved repair when the cause is checked. The AI can help watch the result without taking control of the live shop.
The idea behind this story
A useful diagnosis helps someone act; it does not give the AI permission to act.
Which details would help the website owner decide, and which action should still need their approval?
The technical connection: Read-only incident assistance
Read-only assistance lets an AI inspect approved service information and summarize problems without changing the live system. Permission to diagnose and permission to repair are separate, even when a diagnosis looks convincing.
Advanced: Better diagnosis does not authorize remediation
Choose an incident-assistance loop that reduces operator load without turning uncertain diagnosis into production writes.
Service operations · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. An on-call team receives noisy service alerts and wants an agent to assemble useful evidence before an operator chooses a response.
Your initial decision
How should the agent assist when an alert fires?
User-visible error and latency signals determine paging; an agent must not suppress a critical page.
The approved runbook identifies read-only metrics, recent deployment metadata and sanitized trace summaries.
Production mutation is reserved for the incident commander; customer payloads and secrets are excluded from the evidence packet.
An illustrative 60-second collection budget limits repeated tool calls before the agent hands off what it has.
Compare the alternatives
Improve the runbook and deterministic dashboard
A deterministic view is predictable and cheap, though it may not summarize evidence across varied incident narratives.
Collect a bounded read-only evidence packet
A fixed collection workflow plus source-linked summarization reduces lookup work, but the operator still diagnoses and approves intervention.
Let a read-only agent choose diagnostic queries
An adaptive investigator can pursue unusual symptoms within the same tool and time limits, but variable query sequences may exhaust the budget before collecting basic evidence.
Mechanism, trade-offs, and evidence
Keep alerting anchored to user-visible symptoms rather than generated confidence; the assistant must not become a new single point of paging failure.
Use trace IDs and artifact versions to connect observations, with payload minimization and appropriate telemetry access.
Require each suggested cause to cite a signal and distinguish observation from inference.
Measure operator time to useful evidence, misleading summaries and collection failures against the existing dashboard.
Reconsider after a change
A candidate model ranks causes more accurately in incident replays, but the next rollout introduces an untested failover topology.
What should the higher diagnostic score change during the rollout?
A vendor reports a higher diagnostic benchmark score; in an illustrative local held-out replay, correct top-ranked causes rise from 72 of 100 to 86 of 100 using fixed evidence packets, not adaptive query loops.
The new topology changes dependency and failover behavior, so historical repair sequences may be invalid.
Mutation authority still belongs to the incident commander and the paging contract is unchanged.
The team can add topology metadata and run recovery drills outside production.
Compare the alternatives
Switch to a bounded adaptive diagnostic loop
The improved model might discover new dependencies through read-only queries, but packet-based replay scores do not test query selection, budget exhaustion or the changed topology.
Use a topology-aware dashboard without summaries
Direct dependency and symptom views avoid generated diagnostic errors, but operators resume the cross-service synthesis that the packet workflow had reduced.
Keep the bounded packet and add topology metadata
The candidate improves cause ranking inside the tested collection workflow, while topology checks and operator diagnosis remain necessary; missing dependencies are surfaced rather than inferred.
Mechanism, trade-offs, and evidence
The recommendation stays advisory even with local improvement: packet-based cause ranking improved, but adaptive investigation and repair remain untested in the new topology.
Inspect the remaining misdiagnoses and model-version traces rather than relying solely on the improved average.
Re-evaluate the evidence collector on the new topology and keep incomplete packets visibly incomplete.
Promotion to remediation would need separately demonstrated recovery behavior and explicit authorization, not a higher diagnostic threshold alone.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Two colleagues are choosing a supplier for the office. One says a supplier is approved because its prices were checked. The other means it has passed the company's safety review. Their AI helpers combine both notes into a list headed Approved.
The problem: Stop a shared label from hiding an unfinished check, so the person choosing the supplier can see what has actually been reviewed.
Picture the situation: Compare the price and safety props before looking at the combined folder; one shared heading can hide two different meanings.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Prices checked
One colleague labels the supplier approved after checking its prices.
Safety review expected
Another colleague uses approved to mean the safety review is complete.
One combined supplier list
The AI puts both colleagues' notes under the same heading.
What would you do?
What would help the team before adding more AI helpers?
Ask a third AI which meaning is more commonWhy this choice?
A common meaning is not necessarily your company's meaning. The person responsible for supplier approval needs to settle which checks count and what remains unfinished.
Connect the helpers so they exchange notes fasterWhy this choice?
Faster note sharing would spread the same misunderstanding. Agree what the labels mean before asking software to pass them around.
Agree the checks and show each one separatelyWhy this choice?
Have the supplier owner define approval. Show price review and safety review separately, with who checked each and what is still unknown. One shared list can then support a clear decision.
What to take away
Agree what the words mean before connecting the tools. A tidy combined list should not turn an unfinished check into approval.
What if something changes?
The team now agrees on the labels. An outside safety reviewer must do a two-day check in their own system. They can accept review requests and send progress updates. Your company allows the public product sheet to be shared, but not internal price notes.
How should the team arrange this outside review?
Send the whole shared folder so the reviewer has contextWhy this choice?
The reviewer needs enough information for the safety check, not everything the company holds. Internal price notes are not approved for sharing. Keep them local even if sending one folder would be easier.
Send an agreed review request with the public product sheetWhy this choice?
Name the requested check, who owns it, how progress returns and how to cancel. Share only the approved product sheet. Keep the supplier marked awaiting safety review until the supplier owner checks the returned result.
Have the local AI mark safety complete from the product sheetWhy this choice?
Reading a product sheet is not the outside safety review the company requires. The shared labels are clearer now, but the missing check still needs the responsible reviewer.
What to take away
A separate reviewer now makes a clear handoff useful. Agree the work, the return message and what may be shared; keep final supplier approval with its owner.
The idea behind this story
Shared words need shared meanings; shared work needs clear ownership.
Which label at your workplace could mean two different things to two different people?
The technical connection: Shared vocabulary and task handoffs
A shared vocabulary defines what labels mean. A task handoff tells another system what work to do and how to report progress. Connecting systems does not settle the meaning of approval or grant permission to share private notes.
Advanced: A transport protocol cannot define the business
Choose between a simple research workflow and cross-team delegation while preserving shared meaning and data rights.
Research coordination · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A team compiles supplier research from approved public documents and licensed internal notes, with a human owner deciding what may be shared.
Your initial decision
What architecture should the first research workflow use?
All research runs inside one application under one team's ownership.
The illustrative task compares 4 suppliers using a stable evidence template and a shared approved source list.
Terms such as verified supplier and financial risk need explicit definitions accepted by the human research owner.
Licensed notes may inform internal review but cannot be redistributed to an external service.
Compare the alternatives
Delegate specialist analyses through explicit task contracts
Separate contexts and versioned task artifacts can support distinct legal and technical analyses, at the cost of reconciliation, lifecycle handling and additional calls.
Extract research into a custom asynchronous job service
A job API offers an explicit request, result and cancellation boundary, but adds service deployment and compatibility work to a workflow still owned by one application.
Keep one workflow and a shared evidence schema
A shared vocabulary, source links and bounded tool calls keep ownership clear, but the team must review conflicting source claims.
Mechanism, trade-offs, and evidence
Distinguish tool access, agent coordination and business meaning: these are separate design decisions.
Start with a typed artifact containing the supplier, claim, source, date and unresolved disagreement.
Enforce data rights before retrieval and outbound sharing; a shared context is not permission to copy licensed material.
Compare completed research quality and reviewer reconciliation time, not the number of specialist agents.
Reconsider after a change
An independent partner now performs a long-running specialist assessment in its own system and requires asynchronous progress and cancellation.
What is the smallest justified cross-system integration?
The partner cannot expose its internal tools or state and supports the A2A task contract.
The teams have agreed on a versioned vocabulary and a shareable artifact schema, including unknown and disputed states.
Only approved public-source identifiers and explicitly cleared summaries may cross the boundary; internal notes stay local.
Each system keeps its own scoped tool credentials; cancellation, expiry and artifact rejection must be tested.
Compare the alternatives
Delegate through A2A and keep governed tool access local
A2A carries task status and artifacts while each agent uses its own tools, including MCP where already supported; interoperability and lifecycle testing add work.
Use a bilateral job API with the same sharing contract
A custom asynchronous endpoint can be smaller for a fixed partner, but both teams must maintain status, cancellation and compatibility semantics.
Keep one workflow and import partner reports manually
Human-cleared report imports preserve local processing and avoid a protocol integration, but progress tracking and cancellation become manual coordination tasks.
Mechanism, trade-offs, and evidence
The architecture changes because the ownership and lifecycle boundary changed, not because multi-agent collaboration is inherently superior.
A2A addresses remote tasks, MCP addresses tool interfaces and the shared vocabulary addresses meaning; none replaces the other.
Test stale status, duplicate callbacks, rejected artifacts and cancellation with real protocol implementations before relying on the handoff.
Have the human research owner review conflicts and external sharing; a remote agent's confidence is not a business approval.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
You are helping an AI sort incoming questions for a community centre. Each time it gets one wrong, you adjust its instructions and try the same ten practice questions again. Today it gets all ten right. New messages arrive tomorrow.
The problem: Find out whether the AI can handle new questions, rather than only the ten you have been using to coach it.
Picture the situation: The familiar cards return during practice, while the unopened messages represent questions the helper has not yet had to handle.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Ten practice questions
You use the same set to try out the AI helper.
Try, adjust, try again
After each mistake, you change the instructions and repeat those questions.
New messages tomorrow
The centre will receive questions that were not in the practice set.
What would you do?
What would tell you more than another perfect practice score?
Ask a colleague to write new, realistic test questionsWhy this choice?
Have the colleague use approved centre information, not private visitor messages. Keep the new questions out of the coaching work, agree the right destinations before testing, and compare the old and new instructions on the same fresh questions.
Run the same ten questions three more timesWhy this choice?
Repeated runs can show whether answers vary, but these are still the questions used to improve the instructions. They do not tell you much about handling a new request.
Swap a few words in the same ten questionsWhy this choice?
Small wording changes can be useful practice, but they may keep all the same clues. Ask for genuinely new situations, including questions the AI should send to a person.
What to take away
Keep some realistic questions separate from practice. Getting better at the practice set is useful, but it is not yet a reason to rely on the AI with new messages.
What if something changes?
A colleague tests both versions on 30 fresh questions with answers agreed in advance. The new instructions sort more correctly, including urgent questions that need staff. Staff have time to review suggestions, but no one has tried the helper alongside a normal working day.
What is a useful next step now?
Let the AI send and route all messages without staffWhy this choice?
The fresh test supports trying the helper, not handing over the inbox. A normal day may contain questions the test missed. Keep staff responsible for replies and routing while you learn how it behaves.
Keep editing until it gets every fresh test question rightWhy this choice?
That would turn the separate test into another practice set. Save this result, try the unchanged version beside staff, and use a new untouched test for later changes.
Try its suggestions beside staff without sending or moving messagesWhy this choice?
Keep the tested instructions unchanged. In the centre's approved workspace, let staff compare suggestions with their own decisions and note mistakes and review time. Keep the old version available. A small observed trial can show whether the improvement helps during real work.
What to take away
Fresh results can justify a small, supervised next step. Keep this version unchanged while observing it, and do not quietly turn the separate test into more coaching material.
The idea behind this story
Practise on one set of questions; check progress on another.
How could you tell the difference between learning the task and learning the practice answers?
The technical connection: Held-out evaluation and shadow mode
Held-out evaluation uses questions kept out of improvement work. Shadow mode lets a candidate make suggestions alongside the current process without acting on them. Here, only the instructions changed; the underlying AI model did not.
Advanced: Improve the harness without moving the goalposts
Separate prompt search, runtime changes and weight training, then decide what independent improvement evidence warrants.
Evaluation and adaptation · 10 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A team wants a support-routing agent to improve from failures, but its current optimizer has repeatedly seen the same evaluation tasks.
Your initial decision
What should the team do before declaring improvement?
The illustrative optimizer has selected prompts against the same 80 cases used in the improvement chart.
The current model weights are frozen; proposed changes affect tool-error handling and context assembly.
The optimizer must not edit graders, hidden tests or the production permission policy.
Customer transcripts are not approved for training or synthetic paraphrasing; new tasks must use permitted specifications.
Compare the alternatives
Repair the harness and establish a clean holdout
A manual harness correction plus independently authored tests is slower than accepting the search chart, but creates interpretable evidence.
Continue bounded search for candidate artifacts only
Search may find useful prompt or runtime candidates, but reused tasks cannot support a release claim without separate evaluation.
Train a routing model on expert-labeled synthetic tasks
Supervised tuning on permitted, independently labeled specifications could improve stable routing behavior, but adds dataset and checkpoint maintenance before the runtime defect is isolated.
Mechanism, trade-offs, and evidence
Name the changed object: this proposal changes the harness around frozen weights, not the model weights or necessarily the improvement procedure.
An RSI survey is a taxonomy and research roadmap, not proof that each local iteration compounds or generalizes.
The existing Meta-Harness source distinguishes held-out classification and math results from coding results that reuse search tasks; preserve that distinction here.
Keep training, selection and final evaluation separate, and do not assume synthetic rewriting removes privacy or contamination concerns.
Reconsider after a change
An independent evaluator has tested a frozen harness candidate on a previously unseen task set with protected graders and a documented data origin.
What rollout, if any, is justified by the new evidence?
In the illustrative 200-case holdout, the baseline routes 160 correctly and the candidate routes 178 correctly; both use the same frozen model and call budget.
Reviewers independently adjudicated disagreements and checked critical routing and refusal slices; finite coverage still leaves residual risk.
The synthetic latency target is met, and rollback restores the previous harness artifact without changing model weights.
The owner can monitor a read-only shadow rollout before approving a narrow live canary; no automated permission changes are allowed.
Compare the alternatives
Start an independently evaluated supervised tuning study
A small routing checkpoint might eventually reduce inference costs, but the held-out gain already came from a harness fix and supplies no evidence that tuning adds value.
Promote the frozen harness to monitored shadow evaluation
Run it beside the baseline without taking customer-facing actions, then consider an owner-approved canary if live-distribution evidence holds.
Keep the manual repair and expand targeted evaluation
Retaining the baseline repair limits change while experts add missing risk cases, but delays the independently measured benefit of the selected harness.
Mechanism, trade-offs, and evidence
The decision changes because independent evaluation now exists and isolates the harness change; the numerical results are fictional practice facts, not claims about the cited papers.
The aggregate gain is not enough alone: inspect critical slices, resource use and reviewer disagreements before interpreting it as useful.
Shadow mode checks transfer to current traffic without letting the candidate act; live execution still requires explicit owner approval.
After promotion, preserve this holdout as a recorded final evaluation and create fresh protected evidence for later candidate selection.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
You are on a noisy bus, trying to find an appointment at the local advice centre. The website offers an AI voice helper. You do not want to say personal details aloud, and the bus noise makes speech hard to catch.
The problem: Let someone find a suitable time privately and correct mistakes, without making speech the only way to use the service.
Picture the situation: Read the appointment goal beside the noisy bus setting, then consider what the offered microphone would mean for someone there.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
An appointment to arrange
You want to find an available time at the advice centre.
A noisy bus
Other passengers can hear you, and the bus rattles as you speak.
A voice helper is offered
You have opened the appointment page on your phone.
What would you do?
What would make this service useful on the bus?
Ask people to speak louder and repeat personal detailsWhy this choice?
That might improve some recognition, but it does not solve privacy or help someone who cannot speak. People need another way to complete the task.
Offer typing, visible answers and a staff contact routeWhy this choice?
You can check available times without speaking to the whole bus. Keep speech optional and let people correct their request. The helper only looks up times; choosing a suggestion must not silently book or change an appointment.
Tell people to come back when they can speak somewhere quietWhy this choice?
A quiet room may help some people, but not everyone can wait or use speech. A service with typing and staff contact can help in more situations.
What to take away
Give people a usable choice of input and a way to check the answer. Speaking should be an option, not an entry requirement.
What if something changes?
Later, you are home with a good connection and would rather speak than type. The centre has tried optional voice with people with varied speech and hearing needs. Its tested version shows editable text, has a clear microphone stop button and only looks up available times.
Which option fits this situation now?
Let people choose voice while keeping typing and staff helpWhy this choice?
Optional voice now fits your preference and the tested setting. Keep the words and times visible, allow corrections and stop the microphone when asked. If the connection drops, explain what happened and offer typing or staff help. No appointment is booked by this helper.
Make everyone use voice because the trial went wellWhy this choice?
A successful trial does not remove the noisy bus, privacy concerns or different access needs. Keep typing and staff help available without extra hurdles.
Keep voice unavailable because typing worked on the busWhy this choice?
Typing solved one situation; it is not everyone's easiest route. A tested, optional voice path can help people who prefer speaking without taking typing away.
What to take away
The best route can change with the person and place. Add a tested option without taking away the routes other people still need.
The idea behind this story
Offer another way in, not a new requirement everyone must meet.
When would you choose speech, and when would you want the same task to stay silent?
The technical connection: Multimodal access
Multimodal access means offering more than one way to interact, such as typing and speaking. People need visible corrections, control of the microphone and an alternative when a mode does not suit them. Audio recording needs separate consent.
Advanced: Voice should add a way in, not remove one
Balance conversational speed with correction, privacy and access for users who cannot or do not want to speak.
Accessible service design · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A public information service wants spoken answers about opening hours and appointment availability, without booking or changing appointments in the pilot.
Your initial decision
Which interaction should the first pilot offer?
Users include people with speech differences, hearing loss, shared-device privacy concerns and unreliable mobile connectivity.
No representative speech evaluation exists yet; a provider demo used quiet-room speech only.
The service must offer keyboard and text access, visible answers and a human contact route.
Audio retention is off by default; any research recording requires separate informed consent and a deletion policy.
Compare the alternatives
Offer opt-in streaming voice alongside the text service
Streaming can reduce turn-taking friction while preserving text access and microphone controls, but untested interruption handling and weak connections may create confusing partial turns.
Add push-to-talk with editable transcripts
Explicit turns and correction reduce conversational fluidity but expose recognition errors before the answer is used, with clear microphone activation and cancellation.
Launch text-only while evaluating representative speech tasks
Text avoids untested audio processing but postpones benefits for people who prefer or need speech input.
Mechanism, trade-offs, and evidence
Start with access to correct information, not humanlike conversation; speech input and speech output are independently optional capabilities.
An editable transcript helps users correct recognition, but it is not a reason to remove other input methods.
Evaluate task completion with relevant users and conditions while minimizing collected audio and explaining its use.
Treat WCAG as accessibility requirements to implement and assess, not a badge conferred by choosing a speech provider.
Reconsider after a change
Consented usability trials and independent task checks now support an optional streaming conversation mode on qualified connections, while weak-network users still need the existing path.
What should the service change after these results?
Illustrative trials cover 60 consenting participants across the pilot's speech and hearing access needs; they do not establish performance for all populations.
On qualified connections, the synthetic 2-second response-start target is met and all tested interruption and correction tasks pass; weak connections still miss the target.
The streaming path performs only read-only information lookup, with visible transcripts, a microphone indicator and a working stop control.
Text, push-to-talk and human support remain available without extra hurdles; audio storage remains opt-in and purpose-limited.
Compare the alternatives
Keep push-to-talk as the default in unqualified settings
Explicit turns sacrifice some speed but remain easier to correct where connectivity or user preference does not fit streaming.
Keep the release text-first while broadening speech research
Further recruitment could uncover missing access needs and simplify the immediate release, but defers an optional mode already supported for the qualified pilot group.
Add opt-in streaming with immediate fallback
Qualified connections gain faster turn-taking, while cancellation, connection checks and parallel accessible paths add maintenance.
Mechanism, trade-offs, and evidence
Change the recommendation because representative, task-specific interaction evidence improved, not because a provider announced a better speech benchmark.
Keep the tested scope narrow and distinguish response-start latency from full task completion and correctness.
Use ongoing feedback to find unrepresented access needs and regression cases, without claiming the finite pilot proves universal accessibility.
Provide an understandable fallback when quality drops; silence, stuck playback or an invisible mode switch is not graceful recovery.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Your small team has time to improve one job this month. Copying the same figures into a weekly report takes six hours. Sorting unusual supplier requests also feels slow, but nobody has timed it. A colleague suggests building an AI helper for those requests.
The problem: Choose a first project that frees useful staff time, including the time people will spend checking results and fixing mistakes.
Picture the situation: The report and request pile are two different jobs competing for the single project space shown on the right.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Six hours copying figures
The weekly report uses the same agreed figures and layout each time.
Supplier requests pile up
Unusual requests feel slow, but the team has not measured the work.
Room for one project
The team can tackle only one improvement this month.
What would you do?
Which project has the clearest starting point?
Build the supplier AI first because it sounds more capableWhy this choice?
It might become useful, but you do not yet know where staff time goes or which supplier information may be used. A more capable tool is not automatically the more useful first project.
Ask AI to rewrite the report figures each weekWhy this choice?
The figures and layout already follow fixed rules. Having AI recreate them adds something else to check. A scheduled report can copy the agreed figures without asking a model to interpret them.
Schedule the fixed report and check its totalsWhy this choice?
This tackles a measured, repeatable job without needing AI. Compare the totals with the current report and count the checking time. The six hours are a starting point, not a promise that every minute will be saved.
What to take away
Start with a job you understand and count the whole effort. Ordinary automation may be the best first improvement, even when an AI project sounds more exciting.
What if something changes?
The scheduled report is working. Staff now time supplier requests: ten minutes each. In a separate trial using permitted information, AI suggestions take six minutes per request including staff checks and corrections. Someone can monitor a small trial. The helper can recommend next steps but cannot place orders.
What is worth trying with the next project slot?
Keep polishing the report without finding another report problemWhy this choice?
The report improvement is already doing its job. More polish might help if staff name a remaining problem, but the measured supplier work now gives you a concrete next opportunity.
Try supplier suggestions with staff approval on a small batchWhy this choice?
The trial suggests four minutes saved per request after checking, not guaranteed savings. Keep orders with staff. Count monitoring time and service costs as well, and stop or adjust the trial if errors or extra work outweigh the benefit.
Let the helper place orders to save the remaining six minutesWhy this choice?
Those six minutes include the staff review that made the trial acceptable. Removing it changes the job being tested. Faster suggestions do not show that the AI can safely commit the team's money.
What to take away
A different project can become worthwhile once you know the work and the checking cost. Try the measured opportunity without handing over spending authority or promising savings you have not seen.
The idea behind this story
Choose the useful time saved, not the most impressive tool.
What checking or follow-up work would you count before saying an automation had saved your team time?
The technical connection: Net value and bounded pilots
Net value counts the benefit after review, mistakes and running costs. A bounded pilot tries a small, defined piece of work before expanding. Time freed is not automatically money saved, and recommending a purchase is not permission to make it.
Advanced: Fund an outcome, not an autonomy level
Compare a simple automation and an agent investment, then revisit the portfolio when measured workload value changes.
Product and investment decisions · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. A small operations group can fund one workflow improvement and wants to choose using user benefit, full delivery cost and acceptable risk.
Your initial decision
Which project should receive the first delivery slot?
The illustrative weekly report takes 6 staff hours using stable SQL definitions; a deterministic scheduler and validation checks can remove most repetitive work.
An alternative procurement exception-triage agent has no measured task baseline, uncertain operational data rights and authority to recommend but not place orders.
The team has capacity for one small integration and no dedicated model operations role.
Reported benefits must subtract review, recovery and ongoing service costs rather than count every generated output as a success.
Compare the alternatives
Run a small manual procurement discovery study
Observing tasks and data permissions buys information about a possible larger opportunity but delays a delivered workflow improvement.
Build an advisory triage prototype with synthetic inputs
A sandbox prototype can clarify integration feasibility without operational data or purchasing tools, but its synthetic workload cannot establish demand or realized savings.
Schedule and validate the stable report
Deterministic execution addresses a measured recurring cost with little model risk, but does not handle open-ended procurement research.
Mechanism, trade-offs, and evidence
Frame both projects in terms of accepted user outcomes and constrained delivery capacity, not a contest between old and new technology.
The report has known definitions and a deterministic solution, so model reasoning would add variability without an identified benefit.
Count realized capacity only after confirming that scheduling and validation reduce total human effort.
Record the procurement assumptions for later discovery; deferring an uncertain project is not a claim that agents cannot help it.
Reconsider after a change
The report automation is operating reliably; independent discovery now identifies a bounded exception-triage workload with permitted data and measurable review savings.
What should receive the next available delivery slot?
In this synthetic workload, 200 weekly exceptions require 10 minutes each in the current process; held-out, human-adjudicated trials show an agent-assisted path needs 6 minutes including review and corrections.
Illustrative gross capacity released is 800 minutes per week before operations costs; ongoing monitoring is estimated at 120 minutes and inference at $40 per week.
The trial meets the team's predefined critical-error gate, but the rollout is limited to recommendations with human approval and no purchasing tools.
The authorized owner can support a reversible canary and will measure realized capacity, errors and subgroup effects before further investment.
Compare the alternatives
Pilot bounded agent-assisted exception triage
Model-driven evidence gathering can reduce varied case-handling effort, while review, monitoring and inference remain costs; benefits depend on available reviewer capacity, not just token prices.
Implement deterministic rules for the repeatable exception subset
Rules may be cheaper and easier to audit for recurring cases but do not address evidence-dependent exceptions outside that subset.
Run another broad discovery cycle before a canary
More interviews and manual observations might identify a larger opportunity, but repeat information gathering while the bounded triage workflow already has local evidence and an owner.
Mechanism, trade-offs, and evidence
The portfolio choice changes because one opportunity is already delivered and the next now has a defined task, lawful inputs and local evidence.
The illustrative arithmetic is 200 multiplied by 4 minutes saved, less monitoring effort; money savings additionally require a defensible labor-value and redeployment assumption.
Keep purchasing authority out of scope because triage evidence says nothing about safe transactions.
Predefine canary stop conditions for critical errors and review burden, and revisit the investment if realized value falls below the simpler rules baseline.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Maya joins a community garden. She needs to know where to collect a key, when to water and whom to ask about a plot. The organizer keeps an up-to-date welcome sheet.
The problem: Maya needs a clear starting point, not a new helper that guesses the garden rules.
Picture the situation: The newcomer, welcome sheet and key cubby show the arrival, the available information and the first practical question to resolve.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
First day at the garden
Maya arrives with a bag of seeds and several questions.
A welcome sheet
The organizer has written down the usual first steps.
Where do I start?
Maya needs the key collection point before she can begin.
What would you do?
What would help Maya most right now?
Show her the current welcome sheetWhy this choice?
That gives Maya the actual first steps without another system to learn. Point out the key collection details and the organizer to ask if something is missing.
Have AI design her whole gardening weekWhy this choice?
A personal plan might be fun later, but it could bury the key information or invent rules. First help Maya find the approved basics.
What to take away
When the need is finding a known answer, make that answer easy to find before building something more elaborate.
What if something changes?
The garden joins a network of sites. Welcome information is now spread across several approved pages. A helper has been tried on fresh questions: it shows the right page or sends missing answers to an organizer.
What could help newcomers connect the steps now?
Keep the welcome pages as the only way inWhy this choice?
The pages are still a useful backup, but they no longer connect all the steps. Try the checked helper where the information is current, while keeping direct page access.
Try the checked helper alongside the pagesWhy this choice?
That addresses the new difficulty. Keep its source links visible and let the organizer decide plot assignments or exceptions; the helper should explain the pages, not make garden policy.
What to take away
More varied questions can justify a helper when its answers can be checked and someone owns the exceptions.
The idea behind this story
Add help for the difficulty people actually have, without handing it decisions that belong to someone else.
Which first-day question needs a clear page, and which needs the person who owns the rule?
The technical connection: Grounded onboarding assistance
A workplace helper can answer from approved, current sources and hand off exceptions. That does not authorize it to decide benefits, accommodations or employment outcomes.
Advanced: Help a new colleague without inventing their benefits
Start with a clear welcome checklist, then decide whether varied questions justify a scoped answer assistant.
HR onboarding · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. An HR operations team wants new employees to find first-week tasks without exposing personnel files or making eligibility decisions.
Your initial decision
What should the team offer for the first onboarding release?
The fictional pilot has 18 recurring tasks; most questions ask where a form is or when orientation starts.
HR has approved a current checklist for each location, but benefit exceptions require an HR policy owner.
The helper has no access to medical records, performance reviews or other employees' personnel files.
Hiring, rejection, benefit eligibility and accommodation decisions remain outside the helper's authority.
Compare the alternatives
Publish the location-specific welcome checklist
A maintained checklist answers the repeated navigation questions directly, but staff still handle unusual wording and missing tasks.
Draft answers from permitted onboarding pages
A source-linked assistant can interpret varied questions, but requires access filters, freshness checks and tests for unsupported answers.
Generate a tailored first-week learning plan
Employee-selected interests could make orientation feel personal, but planning adds choices when the immediate difficulty is finding required tasks.
Mechanism, trade-offs, and evidence
Separate a navigation problem from a policy decision: locating a benefits page does not establish a person's entitlement.
Compare time to find the right task and unanswered questions against the current checklist, not chat volume.
Let HR own the content and exception path; a helpful interface cannot acquire authority by sounding confident.
Reconsider after a change
After a merger, approved onboarding pages span several locations and new employees ask questions that combine tasks; a source-answer pilot now has independent evidence.
Does the new question pattern justify adding an answer assistant?
An independent illustrative set of 90 permitted questions includes location conflicts and questions with no approved answer.
The candidate links the applicable source on 84 questions and hands off the remaining 6; this finite result is not a guarantee.
Access and effective-date tests pass for the pilot locations; HR staffs the unresolved-question queue.
Personal eligibility, accommodations and employment decisions still go to HR; employees can always use the checklist.
Compare the alternatives
Keep the checklist as the only entry point
Direct navigation remains predictable and accessible, but now leaves employees to connect related steps across several approved pages.
Pilot source-linked answers in tested locations
A bounded assistant can connect approved steps and hand off uncertainty, but needs ongoing checks for source changes and misplaced confidence.
Expand optional personal orientation plans
A preference-based planner may help later learning, but it does not resolve which approved location-specific requirement applies today.
Mechanism, trade-offs, and evidence
The task changed from finding a known entry to connecting approved information; that is new evidence for a different interface.
Independently reviewed answers and appropriate handoffs justify a limited trial, not a promise of correct answers for every employee.
Monitor wrong-location answers and HR escalation load; neither hiring nor individual rights belongs in the assistant's action space.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Sam helps manage bills in a shared house. A repair invoice arrives. His housemate must approve the amount before payment, and their payment app sometimes freezes after the Pay button is pressed.
The problem: A bill can look correct while payment is still unapproved or its result is unknown.
Picture the situation: Read the bill, the housemate and the uncertain payment screen as separate parts of the problem, not a completed payment.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
The repair bill arrives
The invoice lists the repair, the amount and the person to pay.
A housemate must agree
Sam needs approval before spending the shared money.
The app sometimes freezes
A frozen screen does not show whether money moved.
What would you do?
What should Sam ask the helper to do first?
Press Pay as soon as the bill matchesWhy this choice?
Matching the repair does not provide approval or prove a payment failed. Have the housemate approve the details, and check payment history if the result is unclear before trying again.
Prepare the bill details for approvalWhy this choice?
Show the work, amount and verified recipient so the housemate can decide. Keep payment in the familiar process for now, and independently check any request to change bank details.
What to take away
Checking a bill, approving spending and confirming payment are different jobs. Do not let one stand in for another.
What if something changes?
The house switches to a payment service that records each approved bill and shows its payment status. In a practice run, sending the same approved bill again did not make another payment. Sam can stop the helper at any time.
What small next step makes sense?
Let it submit a small, approved billWhy this choice?
Try one within the agreed limit, keeping the housemate's approval tied to the exact amount and recipient. Check the recorded result; if it is unclear, resolve that payment instead of creating another.
Let it pay any matching bill from now onWhy this choice?
The better service fixes part of payment handling, not permission to spend. Keep the agreed limit and approval, and separately verify new recipients or changed bank details.
What to take away
Better controls can justify a small increase in help. They do not turn a trial into unlimited spending permission.
The idea behind this story
Let approval and a reliable payment record come before automatic submission.
If the screen froze after you paid, where would you check before pressing Pay again?
The technical connection: Approval-bound transaction execution
A payment system binds approval to exact details and records an operation so retries can be reconciled. Provider-specific behavior must be tested; it is not a universal guarantee against duplicate payments.
Advanced: A matched invoice is not permission to pay
Separate invoice matching, payment approval and execution before allowing automation to reduce re-entry.
Finance and accounts payable · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A finance team wants to match supplier invoices to purchase orders and receipts without paying twice or accepting fraudulent bank changes.
Your initial decision
Where should the invoice assistant stop with the current payment connection?
The fictional queue contains 75 invoices; purchase-order, receipt and invoice totals must agree before approval.
A finance approver must authorize the payee, amount and due date; supplier documents cannot authorize a bank-account change.
The existing payment adapter cannot reliably distinguish a lost response from a failed payment.
Supplier identity and bank changes require an independent verification process outside the invoice email thread.
Compare the alternatives
Use exact matching rules without extraction
Rules make amount and reference comparisons reproducible, but staff must enter fields from the varied invoice layouts in this queue.
Prepare matching evidence for finance execution
Extraction with linked invoice fields reduces document hunting while finance checks the match, approves payment and uses the established console.
Submit approved payments through the current adapter
Approval-bound submission would remove re-entry, but an ambiguous payment response still leaves the team unable to reconcile safely.
Mechanism, trade-offs, and evidence
Treat extraction, deterministic matching, human authorization and payment execution as separate steps with separate failure evidence.
A correct match can still contain fraudulent payee instructions; independently verify changed bank details rather than trusting document content.
Do not retry an unknown payment as a new operation; staff need authoritative payment state, not a model guess about whether it worked.
Reconsider after a change
Finance has added a payment gateway with durable operation records, approval-bound requests and reconciliation; failure tests now cover the missing execution controls.
What may the assistant do once the guarded payment path is ready?
In 160 independent illustrative sandbox trials, duplicate delivery and lost responses produced no duplicate payments; this is not a production guarantee.
Server-side approval binds the verified payee, invoice, amount and expiry; a change invalidates approval.
A finance-approved pilot caps each payment at $200 and daily execution at $1,000; exceptions and bank changes still require separate review.
Unknown outcomes wait for reconciliation under the same operation record; a finance operator monitors the queue and can disable submission.
Compare the alternatives
Return every invoice to manual field entry
Exact matching after human entry avoids extraction mistakes, but discards useful evidence preparation without addressing the now-repaired execution issue.
Keep evidence packets with console payment
Staff execution preserves the familiar fallback and recovery routine, but approved invoices still incur a second entry and comparison step.
Pilot gateway submission after finance approval
A bounded submitter removes duplicate entry for approved matches while introducing daily ledger reconciliation and exposure-limit monitoring.
Mechanism, trade-offs, and evidence
The changed recommendation follows repaired transaction controls, not a higher extraction score or a larger language model.
Stripe documents provider-specific retry behavior; verify this gateway's retention and error semantics rather than borrowing an exactly-once guarantee.
Measure correct settled payments and reviewer effort; stopping submission limits new exposure but cannot undo money already transferred.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Leah is booking a room for a club event. The club has a familiar booking checklist. She wants help finding the cancellation terms and deposit amount before the person authorized to book signs.
The problem: A tidy summary can help find terms, but it cannot decide whether the club should accept them.
Picture the situation: The room gives the agreement a purpose; the open pages and waiting checklist show what still needs to be understood.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
A room for Saturday
Leah has found a venue for the club event.
Pages of booking terms
The deposit and cancellation wording appear in different places.
The club booking checklist
The club has questions to answer before anyone signs.
What would you do?
What is a useful job for the helper?
Find the terms and show the exact passagesWhy this choice?
That saves searching while leaving the decision with the authorized organizer. Keep the original wording beside the summary and flag anything the checklist does not cover.
Tell the organizer whether the agreement is safeWhy this choice?
A confident verdict can hide exceptions or missing pages. Ask for the relevant passages instead, and let the organizer seek qualified advice when the terms need interpretation.
What to take away
A helper can organize the evidence for an agreement without having authority to interpret or accept it.
What if something changes?
The venue sends different terms and refers to another document that is not attached. The club checklist does not cover the new cancellation wording. The venue wants an answer today.
What should Leah do before the club agrees?
Use the usual checklist summary to keep movingWhy this choice?
The missing document could change the agreement. A familiar summary cannot fill that gap; request the attachment and flag the unfamiliar terms before anyone commits.
Get the missing document and ask the authorized organizerWhy this choice?
Hold acceptance while the organizer reviews the complete terms and gets qualified advice if needed. The helper can list unanswered questions, but should not guess what the missing document says.
What to take away
Missing terms are missing evidence. A deadline does not make a guessed interpretation safe to accept.
The idea behind this story
Use summaries to support an accountable decision, never to replace missing terms or qualified judgment.
What would you want to see in the original agreement before trusting a summary?
The technical connection: Evidence-linked contract review
Clause extraction helps reviewers find text and omissions. Counsel decides legal interpretation, and authorized humans approve binding terms. This is a workflow example, not legal advice.
Advanced: Find the clause; do not decide its legal effect
Use AI to prepare a contract comparison, then recognize when changed terms require specialist judgment.
Legal operations and contract review · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A legal operations team prepares supplier agreements for counsel using an approved clause playbook; the assistant cannot sign, negotiate or give legal advice.
Your initial decision
How should the assistant help reviewers compare familiar agreement terms?
The fictional workload has 24 agreements based on one familiar template and a current counsel-approved playbook.
Reviewers need exact clause locations and omissions, including referenced schedules, not a general risk score.
Contract text is untrusted evidence; instructions embedded in an attachment cannot change the review rules.
Counsel decides legal interpretation and exceptions; an authorized human approves binding terms and signature.
Compare the alternatives
Have counsel perform the entire first pass
Counsel can examine language directly with no extraction dependency, but routine clause finding consumes time needed for substantive judgment.
Show only a literal template comparison
A text diff reliably exposes changed wording, but cannot reliably locate relocated clauses or resolve cross-references across attached schedules.
Prepare a source-linked clause review packet
Extraction maps clauses and omissions to the approved playbook while counsel checks source spans and decides their significance.
Mechanism, trade-offs, and evidence
The useful delegation is document navigation and comparison, not a legal conclusion about enforceability or acceptable liability.
Evaluate omissions as well as extracted text: an absent schedule can matter more than a fluent summary of the main agreement.
Keep the original documents beside the packet so counsel can challenge the assistant rather than merely approve its wording.
Reconsider after a change
A new supplier proposes an unfamiliar jurisdiction and incorporates an unavailable schedule that may change liability; the approved playbook does not cover this combination.
What should happen to this agreement before anyone promises acceptance?
In the illustrative review, 2 referenced schedules are missing and the governing-law clause is outside the tested template family.
No local evaluation establishes that the assistant can identify the effect of this combination.
Counsel must obtain the schedules and decide whether specialist advice or a playbook update is needed.
Commercial staff may request documents but cannot treat an assistant summary as approval to sign or accept terms.
Compare the alternatives
Route the exception to counsel with missing evidence
Specialist review delays this agreement while missing schedules are obtained, but places an unfamiliar interpretation with its authorized owner.
Apply the familiar template diff to the exception
A familiar comparison offers a quick list of changed words, but its baseline cannot explain unseen schedules or a different legal context.
Keep extraction only as an incomplete evidence aid
Linked passages can still reduce document navigation effort, but the packet must visibly mark missing schedules and exclude out-of-playbook recommendations.
Mechanism, trade-offs, and evidence
The missing information changes the task from familiar comparison to unresolved legal interpretation; better prose cannot fill that gap.
Pause the consequential commitment, not every administrative action: staff can still request documents and organize cited evidence.
This is a review-workflow exercise, not legal advice; the policy owner and counsel determine rights, obligations and approval requirements.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Noor is choosing lunch for a volunteer event. The group has agreed its budget, delivery time and dietary needs. Several caterers have returned the same price form.
The problem: The group needs a fair comparison, not whichever offer sounds most convincing.
Picture the situation: Look from the people needing lunch to the offers, then to the group needs that make those offers worth comparing.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Lunch for the volunteers
People need food they can eat, delivered before the afternoon shift.
Several catering offers
Each caterer has filled in the same price form.
The group requirements
Budget, delivery and dietary needs were agreed before the offers arrived.
What would you do?
How should Noor compare these offers?
Ask AI which offer sounds most impressiveWhy this choice?
Polished wording does not prove food suitability or delivery. Compare the agreed requirements and total costs first, then ask caterers to confirm any unsupported claim.
Compare the agreed needs and complete pricesWhy this choice?
A simple table makes the differences visible. Keep essential dietary requirements separate from price preferences, and let the authorized organizer make the final booking.
What to take away
Agree what matters before comparing offers. Keep must-have requirements separate from attractive extras.
What if something changes?
For the next event, offers arrive as emails, menus and attachments. One price is per tray and another is per person. A tried helper can find the amounts and show the exact source for each.
Where would that helper be useful now?
Prepare comparable figures with source linksWhy this choice?
That addresses the new searching work. Check servings, delivery charges and unclear dietary claims before comparing totals; keep the organizer in charge of the booking.
Sort the quoted prices from lowest to highestWhy this choice?
A tray price and a price per person are not directly comparable. First establish servings and included charges, using the helper to find evidence rather than guess missing quantities.
What to take away
When offers arrive differently, help people prepare comparable evidence before doing the same fair comparison.
The idea behind this story
Improve the evidence going into a decision before adding more opinions about the winner.
What hidden difference could make the apparently cheapest offer cost more?
The technical connection: Evidence extraction and deterministic comparison
AI can locate bid fields and their sources. Fixed calculations compare consistent units, while procurement owners verify important claims and approve supplier awards.
Advanced: Compare suppliers without laundering their claims
Choose a fair comparison method, then adapt when bids stop describing the same thing in the same format.
Procurement and supplier evaluation · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A procurement team compares packaging suppliers against published requirements and needs an accountable recommendation before an authorized buyer awards a contract.
Your initial decision
How should the team compare complete bids with agreed criteria?
There are 6 fictional bids in a common form with price, delivery range and verified product test results.
The procurement owner has fixed required checks and comparison weights before opening bids.
A supplier statement is not proof of certification or performance; conflicts of interest must be disclosed.
An authorized human awards the contract; the tool cannot change criteria to favor a bidder or make a purchase commitment.
Compare the alternatives
Use a checked comparison table and sensitivity analysis
A transparent table computes agreed measures consistently, but reviewers must examine how close results change under plausible cost or delivery variation.
Extract bid evidence into the agreed comparison
Document extraction can link claims to supporting passages, but adds correction and unit-conversion work when the supplied fields are already complete.
Ask independent AI reviewers for a ranked shortlist
Several reviews may surface different concerns, but their consensus can obscure shared assumptions and is less reproducible than the agreed calculation.
Mechanism, trade-offs, and evidence
Separate mandatory qualification from preferences so an attractive price cannot cancel a missing required check.
Keep calculations deterministic and auditable; ask whether changing a plausible delivery assumption changes the recommendation.
Human award authority matters, but useful automation can still calculate totals and highlight missing evidence without manual rechecking of every arithmetic step.
Reconsider after a change
A new tender accepts varied document formats; buyers now spend most of their review time finding delivery conditions and converting price units rather than comparing complete fields.
Which addition addresses the new procurement bottleneck?
An independent illustrative test uses 40 unseen bid documents; 36 produce fully verified fields and 4 are correctly flagged for review.
Every extracted price retains currency, unit, quantity basis and a source span; unverified claims remain visibly unverified.
The procurement owner retains the existing criteria; deterministic calculations reject missing or incompatible units.
A buyer reviews material uncertainties and approves the award; supplier attachments have no authority to instruct tools.
Compare the alternatives
Keep staff entering all fields into the table
Human entry avoids model extraction errors and keeps the familiar comparison, but repeats the measured document-navigation burden for every bid.
Pilot cited extraction into the fixed comparison
Verified field extraction targets the new bottleneck while preserving deterministic scoring, but reviewers still resolve ambiguity and check unsupported claims.
Expand AI panel ranking across all tender documents
A panel can digest long proposals and suggest concerns, but combining rankings still hides whether prices and delivery terms are comparable.
Mechanism, trade-offs, and evidence
The calculation did not become harder; evidence preparation did, so add assistance at that boundary rather than replacing the award process.
The test set is illustrative and separate from development examples; finite success justifies a monitored trial, not guaranteed supplier quality.
Preserve provenance from source span to normalized field to final comparison so a reviewer can challenge any recommendation.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Ari helps at a bakery. Customers ask about cake sizes, prices and collection times. The owner keeps an approved menu and order calendar, and approves any firm order or special promise.
The problem: A friendly reply can become a promise the bakery cannot keep.
Picture the situation: The cake request sits beside what the bakery offers and the work already planned; a promise has not been made.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
A birthday cake request
A customer asks for a cake by Saturday morning.
The current cake menu
The menu lists sizes and prices the bakery offers.
A busy order calendar
The owner needs to confirm space before accepting the order.
What would you do?
How could a helper prepare Ari's reply?
Draft from the menu for the owner to approveWhy this choice?
Use the current price and available options, then have the owner confirm the actual order and collection time. The draft should not turn an open slot into an accepted booking.
Copy a similar promise from last monthWhy this choice?
Last month's price or collection time may not apply now. Check the current menu and calendar instead, and have the owner approve any special request.
What to take away
Use current information for a useful draft. Keep the actual promise with the person authorized to make it.
What if something changes?
The bakery oven breaks. The calendar still shows old collection times. The owner has approved a short message saying orders are being checked and customers will receive an update, without promising a new time.
What should Ari send while the owner checks capacity?
Draft a likely collection time from the calendarWhy this choice?
The calendar no longer proves what the bakery can deliver. Do not turn yesterday's plan into today's promise; wait for the owner to confirm capacity.
Use the approved update messageWhy this choice?
That keeps the customer informed without inventing a collection time. Record who needs a follow-up and let the owner approve a firm offer once capacity is known.
What to take away
When delivery information stops being reliable, a clear limited update is more useful than a confident guess.
The idea behind this story
Do not let helpful wording outrun the evidence or the authority behind a promise.
Which words in a friendly reply might a customer reasonably treat as a promise?
The technical connection: Freshness-gated commercial drafting
Drafts use current approved commercial records. Stale availability triggers a limited status message, while authorized humans retain approval of binding prices, dates and commitments.
Advanced: Draft the offer without promising what you cannot deliver
Help sales describe approved terms, then narrow the message when delivery evidence becomes unreliable.
Sales commitments and revenue operations · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. An account team drafts customer proposals using approved product capabilities, prices and delivery information; a persuasive draft must not create an unsupported commitment.
Your initial decision
How can drafting assistance save time without expanding sales authority?
The fictional catalog has 30 approved offerings with dated capability, price and delivery records.
Sales may draft proposals; an authorized account owner approves binding quotes, discounts and delivery commitments.
Roadmap ideas and internal estimates are not available product features or promised dates.
Customer records are account-scoped; drafts must not reveal another customer's negotiated terms.
Compare the alternatives
Develop bespoke solution proposals for each account
Custom proposals can address complex customer needs, but add engineering review and assumption tracking for otherwise standard catalog requests.
Draft from current approved commercial records
Source-linked drafting adapts the wording to a customer while the account owner checks exact commitments before any binding quote is sent.
Use a standard acknowledgment without delivery detail
A fixed acknowledgment avoids interpreting commercial records, but withholds useful approved information that is currently available for ordinary requests.
Mechanism, trade-offs, and evidence
A draft is not merely prose when customers rely on its promises; identify the exact claims that require commercial authority.
Use current account-permitted records, not past proposals that may contain special terms for a different customer.
Test invented features, expired prices and ambiguous dates alongside useful drafts; a fluent answer is not the success criterion.
Reconsider after a change
A warehouse disruption makes the delivery feed stale and invalidates the usual lead times; operations has issued a short approved holding statement with no new delivery promise.
What should the team send while operations verifies delivery capacity?
The illustrative delivery feed is 36 hours old during a disruption, outside the agreed same-day freshness limit.
Operations owns the revised availability; the model must not turn an old estimate into a new commitment.
The holding statement confirms receipt and promises an update process, not a shipment date.
Urgent exceptions go to operations and the authorized account owner before a binding offer is made.
Compare the alternatives
Develop bespoke alternatives from past delivery patterns
Historical patterns may suggest substitutions for investigation, but cannot establish current stock or authorize promises during an active disruption.
Continue source-linked drafts after freshness is restored
The existing drafting workflow can recover personalized offers, but its delivery sources must be revalidated before those claims appear in outgoing proposals.
Send the approved no-date status acknowledgment
A fixed message maintains customer contact without inventing capacity, but delays a detailed offer and needs a tracked follow-up owner.
Mechanism, trade-offs, and evidence
Freshness was a condition of the earlier recommendation; disruption removes that foundation even if the drafting model is unchanged.
A narrower message still provides service by acknowledging the customer and naming the next step without disguising uncertainty.
Measure missed follow-ups and unsupported promises during recovery; resume richer drafting only after the affected records are trustworthy.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Two housemates share tea and washing-up supplies. They agree that a shopping helper may reorder their usual items below a set amount, within a small spending limit. Anything unusual needs their approval.
The problem: Routine shopping can be easy to automate, but the list must reflect what is actually needed.
Picture the situation: Compare the supplies and agreed shopping list with the parcel already coming before imagining another order joining the picture.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
The usual household supplies
Tea and washing-up liquid run out at a fairly steady pace.
An agreed shopping rule
The housemates have listed the items and spending limit.
An order already coming
An existing order matters when deciding whether to buy more.
What would you do?
What is a sensible job for their shopping helper?
Predict and buy everything they might wantWhy this choice?
That goes beyond the agreed list and may spend money on guesses. Start with the usual items, check what is already coming and ask before any unusual purchase.
Reorder agreed items after checking stock and ordersWhy this choice?
That handles the predictable job within permission already given. Keep the spending limit, avoid duplicate orders and send uncertain or unusual requests back to the housemates.
What to take away
People do not need to approve every tiny repeat if they have clearly agreed the limits and the checks are reliable.
What if something changes?
A party changes what the house needs, and the shared list accidentally repeats several entries. The helper now appears ready to buy far more than usual. One housemate can check the cupboard and existing orders.
What should happen to the unusual order?
Pause it and check the cupboard with a housemateWhy this choice?
Separate real party needs from repeated list entries before spending. The housemate can approve an extra order; unaffected usual items can continue if their counts and limits are still reliable.
Place it because it is under the spending limitWhy this choice?
A cheap unnecessary order is still unnecessary. The limit does not prove the list is right; check the repeated entries and what is already on its way.
What to take away
A spending limit controls exposure, not truth. Question unusual inputs before letting a routine rule act on them.
The idea behind this story
Automate stable, permitted repeats; review changed conditions and uncertain counts before making new commitments.
What would make you distrust a shopping suggestion even if it stayed within budget?
The technical connection: Bounded replenishment and data quality
Fixed reorder rules suit stable inventory under explicit purchasing authority. Duplicate feeds or shifting demand require reconciliation; caps alone cannot make corrupted inputs safe to use.
Advanced: Yesterday's demand is not tomorrow's order
Use bounded stock rules where demand is stable, then respond when a promotion and duplicate feed break the assumptions.
Inventory and supply chain · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A supply team replenishes ordinary packaging supplies and wants fewer stockouts without unnecessary spending, duplicate orders or piles of obsolete stock.
Your initial decision
What ordering approach fits stable demand and an existing purchasing policy?
The fictional pilot covers 12 noncritical items with stable demand, verified stock counts and agreed lead times.
A purchasing owner has explicitly preauthorized repeat orders for listed suppliers within per-item and weekly caps.
New suppliers, higher spend and contract changes require human approval; no model may expand that authority.
The ordering service checks outstanding orders, records durable operation IDs and stops unknown outcomes for reconciliation.
Compare the alternatives
Have a planner approve every routine reorder
Per-order review gives the planner direct visibility, but consumes attention on predictable requests already covered by explicit bounded purchasing authority.
Replace reorder points with an adaptive AI forecast
A forecast might capture patterns that fixed thresholds miss, but adds evaluation and maintenance when stable consumption already supports a simple rule.
Run capped reorder rules for the approved item list
Deterministic rules can place preauthorized repeats with duplicate checks, while exceptional quantities and unknown execution states stop for review.
Mechanism, trade-offs, and evidence
This task does not require an agent to invent a plan: stable inputs and explicit purchasing rules favor a predictable workflow.
Human oversight can approve the bounded policy in advance while still requiring individual approval for consequential exceptions.
Check inventory and open orders at execution time; a valid trigger yesterday may no longer justify another purchase today.
Reconsider after a change
A promotion sharply shifts demand while a feed defect duplicates recent sales; inventory and sales totals now disagree, so the ordinary reorder signals are not trustworthy.
How should replenishment continue while the affected evidence is repaired?
In this illustrative incident, demand appears to triple and 14 sales events have duplicate identifiers.
The planner can verify physical counts and supplier lead times for the affected items before approving urgent orders.
Only the affected item group needs a stop; verified, unaffected items remain within the original authorized rules.
A forecast trained on the contaminated feed cannot establish true demand; purchasing caps still apply.
Compare the alternatives
Pause affected automatic orders for planner reconciliation
Targeted review slows affected replenishment while staff verify counts, but avoids buying against duplicate demand and leaves unaffected routines running.
Fit a new forecast to the promotion feed
A new model could eventually capture promotion behavior, but today it would learn from duplicated events and cannot distinguish real demand from feed errors.
Continue capped rules only on verified unaffected items
Selective continuation preserves routine service outside the incident, but requires a reliable affected-item boundary and must not release blocked purchases.
Mechanism, trade-offs, and evidence
A spending cap limits harm but does not make bad demand evidence true; the changed problem is data integrity plus a distribution shift.
Choose a targeted pause instead of stopping every useful automation or letting an adaptive model explain away corrupted records.
Reconcile existing orders before issuing replacements, and compare restored rules with cleaned demand before considering a more complex forecast.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Rosa organizes a neighborhood activity. A feedback form asks why people miss sessions. Replies include useful scheduling suggestions alongside phone numbers and private family details. Rosa wants to tell the committee which times work best.
The problem: The committee needs a useful pattern, not access to every person's private circumstances.
Picture the situation: The calendar explains the question, the folded replies suggest personal context, and the committee waits for a report rather than individual stories.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Some neighbors miss sessions
Rosa wants to understand whether different times would help.
Personal feedback arrives
Replies mix scheduling suggestions with phone numbers and private stories.
The committee needs a report
Members want to choose meeting times, not read personal case histories.
What would you do?
What should Rosa prepare first?
A reviewed count of preferred timesWhy this choice?
That answers the immediate question without sharing the stories. Ask the person responsible for privacy how to group small numbers so the report does not single someone out.
Remove names and send all replies to a new AI toolWhy this choice?
A rare family detail may still identify someone, and the tool is not approved to receive the replies. Keep them in the approved place and share only what the report needs.
What to take away
Removing names does not make every story safe to share. Start with the least information needed for the question.
What if something changes?
The counts do not explain why suitable times still fail. The privacy lead approves a restricted helper for this purpose, with private details removed before use, limited access and a clear deletion plan. The committee still receives only reviewed themes.
What use fits that new permission?
Use any convenient tool now that summaries are approvedWhy this choice?
Approval for one restricted helper does not permit sending the replies elsewhere. Keep the agreed access and deletion rules, and ask the privacy lead before changing who receives the information or why.
Try the approved helper for reviewed scheduling themesWhy this choice?
That can explore the missing pattern within the agreed limits. Check for identifying details before sharing, and stop if private stories appear in the output. Ask the privacy lead what may be kept, shared or deleted.
What to take away
A clearer need and specific safeguards can justify limited help, without granting permission to share the underlying stories widely.
The idea behind this story
Match what you share, who receives it and their permission to the actual need.
What detail might identify a neighbor even after their name is removed?
The technical connection: Purpose-limited processing
Minimization, approved recipients and output review work together. Privacy owners decide permitted use, rights handling and retention; a successful test or a name-removal step does not establish blanket compliance.
Advanced: A useful summary does not require everyone's private details
Choose the least data a task needs, then assess a restricted summary pilot without treating approval as unlimited access.
Privacy and sensitive data sharing · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A service quality team wants to learn why appointments are missed; its notes also contain contact details and private personal circumstances unrelated to the improvement report.
Your initial decision
What information should leave the case-management system for the first report?
The fictional report needs category counts, not personal narratives; a restricted internal query can produce them.
The proposed external assistant is not approved for these records and has no agreed data-use or retention terms.
Removing names alone can leave people identifiable through rare circumstances, dates or combinations of fields.
The privacy policy owner decides permitted purposes, recipients and rights handling; the model cannot infer consent.
Compare the alternatives
Create reviewed counts inside the approved system
A minimal aggregate report answers the current question without exporting narratives, but small groups still need disclosure review before sharing.
Prepare a restricted summary pilot after approval
A controlled summary could reveal themes beyond existing categories, but requires purpose review, approved processing and tested minimization first.
Remove direct identifiers before external summarization
Redaction can reduce obvious exposure, but rare details can remain identifying and the proposed recipient is still unapproved for this use.
Mechanism, trade-offs, and evidence
Start with the purpose: category counts answer the stated question, so exporting full notes would add exposure without demonstrated need.
Data minimization and recipient authorization are separate checks; passing a redaction test does not grant permission to share.
NIST provides voluntary risk-management guidance, not a finding that this fictional report complies with every privacy obligation.
Reconsider after a change
The counts conceal recurring scheduling obstacles; the privacy owner approves a purpose-limited internal summarizer with tested filtering, restricted access and a defined retention schedule.
Can the team now learn from narratives within the approved boundary?
An independent illustrative test of 100 synthetic notes finds 93 useful theme summaries and flags 7 for restricted human review.
The approved processor excludes contact details before model access, blocks external tools and restricts output to the quality team.
The privacy owner has set retention, access and rights-handling procedures for this specific purpose; rare details still need disclosure review.
Reviewers may correct or withhold themes; outputs must not score individuals or drive eligibility decisions.
Compare the alternatives
Keep the counts-only report as the fallback
Counts preserve the lowest-data option and a stable baseline, but cannot explain the newly observed obstacles hidden inside broad categories.
Pilot restricted theme summaries for the approved purpose
Minimized internal summaries may reveal actionable scheduling themes, but require access enforcement, disclosure review and deletion under the owner's schedule.
Use the redacted notes with the external assistant
An external tool might offer convenient reporting, but the internal approval does not extend to another processor or eliminate re-identification risk.
Mechanism, trade-offs, and evidence
The evidence now supports a question that counts cannot answer, and the approved boundary has changed; both matter to the recommendation.
Synthetic tests are useful safety probes, not proof that real notes cannot identify someone; monitor disclosures and preserve a restricted review path.
Keep rights and retention decisions with the privacy policy owner, and do not turn service-improvement themes into decisions about individuals.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Eli helps a community group manage shared online folders. A volunteer needs to read event plans for a week. The folder owner must agree, but the old sharing tool can only give broad access with no end date.
The problem: The volunteer has a real need, but that does not justify opening every folder indefinitely.
Picture the situation: The volunteer needs particular plans for a short time, while the closed folders and old sharing tool leave that access unresolved.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
A volunteer needs plans
The volunteer is helping with one event next week.
Several shared folders
Some folders contain information unrelated to that event.
A week of help
The request is temporary, but the old sharing tool has no expiry.
What would you do?
What should Eli's helper do with the request?
Give broad access after the volunteer says yesWhy this choice?
The volunteer cannot approve access on the owner's behalf, and broad sharing exposes unrelated material. Ask the owner for the specific folder and duration through the established process.
Prepare a specific request for the folder ownerWhy this choice?
State who needs which folder, why and until when. Let the owner approve and the responsible administrator arrange limited access; do not give the helper the broad sharing power.
What to take away
Knowing who asked is different from knowing they are allowed. Ask for the smallest access that serves the job.
What if something changes?
The group gets a sharing service that accepts the owner's approval for one read-only folder and an end date. Practice checks show access expires and cannot be reused for another folder. The administrator receives an alert if removal fails.
What can the helper now reasonably do?
Carry out the owner-approved, time-limited sharingWhy this choice?
That removes an extra handoff without letting the helper choose permissions. Keep approval tied to the person, folder and end date, and have the administrator resolve any failed removal.
Reuse the approval for other similar foldersWhy this choice?
Similar names do not mean the same permission. Ask for a fresh owner approval when the folder, person or access changes, rather than stretching an earlier yes.
What to take away
Better controls can let a helper carry out a decision. They do not let it expand that decision.
The idea behind this story
Keep access narrow, approved by its owner and removable when the need ends.
What should happen to the permission when the volunteer's week is over?
The technical connection: Scoped, expiring authorization
A server binds approval to an identity, resource, role and expiry. Tested removal matters as much as creation; privileged exceptions still need their responsible security owner.
Advanced: A request for help is not a grant of access
Separate access requests from authorization, then use expiring permissions when the approval and revocation path is proven.
Security and employee permissions · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. An internal help desk wants to speed up temporary project access while preventing a conversational helper from granting broad or lasting privileges.
Your initial decision
What role can an access helper safely take before scoped provisioning exists?
The fictional team processes 20 temporary project-folder requests each week.
An authenticated request still needs resource-owner approval; a manager title in chat is not authorization.
The legacy connector uses a broad service account and cannot bind a grant to an approved resource, role and expiry.
Privileged roles, conflicting duties and employment-status exceptions require security-owner review.
Compare the alternatives
Offer a catalog of standard roles and request forms
A clear catalog reduces vague requests without provisioning access, but staff still translate unusual project needs into the right approval packet.
Prepare narrow requests for owner approval and IT execution
The helper collects purpose, resource and duration while owners approve and IT provisions through the established path, leaving manual execution effort.
Add supervised provisioning after resource-owner approval
Supervised provisioning could reduce re-entry after owner approval, but legacy credentials still exceed the requested scope and removal is not enforced.
Mechanism, trade-offs, and evidence
Identity answers who is asking; authorization answers whether this person may access this resource for this purpose and duration.
Keep request preparation separate from grant execution so the helper cannot become a confused deputy using its broad service account.
Measure time to correctly scoped access and successful removal, not only how quickly a request receives a friendly response.
Reconsider after a change
IT replaces the broad connector with a scoped grant service; resource-owner approvals and expiry are enforced server-side, and independent tests include removal as well as creation.
Which requests may now use the helper's provisioning path?
In 120 independent illustrative tests, replayed, expired and wrong-resource approvals are rejected and scheduled removals complete; finite tests are not a guarantee.
A signed approval binds the employee, read-only role, project folder and end time; employment status is rechecked when executing.
Only a listed nonprivileged project role is in scope; privilege elevation and conflicting duties still require security review.
Failed revocation alerts IT and blocks renewal; every grant has an audit record and an operator disable path.
Compare the alternatives
Use the catalog alone for all project requests
Role descriptions remain useful for orientation, but a catalog alone does not use the tested approval-to-expiry path to reduce the provisioning queue.
Keep IT execution for unsupported and privileged requests
The established packet workflow handles roles outside the service's tested scope, but adds avoidable handoffs if applied to every approved read-only request.
Execute owner-approved expiring project access
Scoped execution removes re-entry for a narrow role while retaining human resource-owner approval and monitored automatic expiry.
Mechanism, trade-offs, and evidence
Adoption is justified by enforceable scope and tested removal, not by the assistant becoming more persuasive about a person's need.
Approval must bind the actual operation so a changed folder, role or employee requires a new authorization.
Review grant and revocation outcomes together; successful creation without reliable expiry would defeat the purpose of temporary access.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Ben helps a club sort its digital archive. It includes receipts, membership forms and event notes. Some folders are old, but nobody has matched all of them to the club's approved keeping and deletion rules.
The problem: Age alone does not tell Ben what may be deleted, what must stay or who gets to decide.
Picture the situation: The crowded shelf contains different kinds of records; the empty tabs show that some keeping decisions have not yet been attached.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
An overflowing archive
Different kinds of club records have accumulated over the years.
Receipts beside member forms
The folders contain records with different purposes and private details.
What can go?
Some records have no clear owner or keeping rule attached.
What would you do?
What is the useful first job for a helper?
List record types and unanswered questions for the ownerWhy this choice?
That helps the responsible person connect records to the right rules. Keep the files unchanged while they resolve uncertain categories, required preservation and any requests about personal information.
Delete the oldest folders to make spaceWhy this choice?
Old does not mean disposable, and deletion may be permanent. First ask the records owner which rules apply and whether anything must be preserved.
What to take away
Sort the evidence before deleting records. A helper cannot invent the rules just because storage is crowded.
What if something changes?
The records owner approves a deletion list for one clearly defined category. The service checks again for records that must be preserved before acting. A trial identifies uncertain files separately, and the owner has set a short recovery period.
How should the approved cleanup proceed?
Also delete similar-looking files to save another reviewWhy this choice?
Similarity does not put a file on the approved list. Keep uncertain records for the owner and check whether anything must still be kept; do not expand a deletion decision by guesswork.
Process only the approved list after the final checksWhy this choice?
That handles repetitive cleanup without making new rules. Stop if a record is now protected, record the outcome and follow the owner's recovery and final-deletion procedure.
What to take away
Once the owner has decided and checks are reliable, a helper can carry out a narrow cleanup without deciding what everyone must keep.
The idea behind this story
Separate organizing records, deciding their rules and carrying out an approved disposal.
Who would you ask before deleting a file whose purpose you do not understand?
The technical connection: Policy-controlled records disposal
Records owners and counsel determine schedules, rights requests and legal holds. Deterministic execution can process an approved manifest with live checks; it cannot infer destruction authority or guarantee compliance.
Advanced: Old files are not automatically disposable
Distinguish records classification from deletion authority, then automate only an approved, hold-checked disposal class.
Records management and compliance operations · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A records team wants to reduce an overflowing archive; the assistant can help locate evidence but cannot decide retention periods, legal holds or a person's rights.
Your initial decision
What should happen before the team enables automatic disposal?
The fictional archive has 8 record classes with incomplete ownership and retention mappings.
The records policy owner and counsel determine applicable schedules, holds and rights requests; file age alone does not settle them.
Some documents may be subject to a legal hold, and the current hold register is not connected to the archive.
Deleting an original may be irreversible; no model-generated classification may authorize destruction.
Compare the alternatives
Run disposal rules after policy and hold controls exist
An approved rules engine could reduce repetitive cleanup, but missing class mappings and live hold checks prevent a safe execution decision today.
Move old records to a cheaper restricted archive
Restricted storage can reduce immediate cost without deletion, but indefinite copying does not resolve retention duties and may complicate discovery.
Inventory record classes for policy-owner review
Evidence-linked classification suggestions expose ownership and schedule gaps while humans resolve uncertainty, but storage reduction waits for those decisions.
Mechanism, trade-offs, and evidence
The bottleneck is missing authority and metadata, not insufficiently clever deletion; first connect records to accountable owners.
Keep classification suggestions reviewable and preserve uncertainty rather than treating an inferred label as a destruction instruction.
This workflow is not legal advice or a compliance certification; applicable obligations and individual rights require the responsible policy owner.
Reconsider after a change
The records owner approves a disposal schedule for a narrow administrative record class, and engineering connects authoritative hold checks with a reviewed disposal manifest.
Can the team automate this approved class without delegating retention judgment?
A fictional dry run covers 300 records: 260 meet the owner-approved schedule and 40 are held or lack required metadata.
An authorized records officer approves the exact manifest; execution rechecks current holds, class and schedule version and rejects any changed eligibility.
A documented recovery window precedes final destruction; any deletion beyond that window may be irreversible.
Unknown classes, active holds and rights requests remain blocked for the records owner; downstream copies follow the owner's separately verified procedure.
Compare the alternatives
Execute the approved manifest with live hold checks
Deterministic disposal reduces repetitive work on a defined class while preserving officer approval, current hold checks and an auditable outcome for each record.
Move the eligible set into indefinite cold storage
Cold storage postpones irreversible deletion, but retaining records indefinitely can conflict with the owner's approved schedule and rights-handling process.
Keep read-only review for unmapped or held records
Inventory review remains appropriate for unresolved records, but repeating it for the approved class delays a now-authorized and tested disposal process.
Mechanism, trade-offs, and evidence
The assistant has not acquired legal authority: the owner established the schedule and an officer approved a concrete manifest.
A dry run is illustrative evidence, not blanket compliance; rechecking holds at execution protects against a valid earlier decision becoming stale.
Record dispositions and failures without retaining deleted content in logs; verify downstream handling rather than claiming one delete clears every copy.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
A school club uses an AI helper to draft meeting notes. A cheaper helper advertises better scores. The club secretary still checks every draft, especially dates and urgent actions, before sharing it.
The problem: A better advertised score does not show whether the new helper preserves the details this club needs.
Picture the situation: Compare the new offer with the club notes and important date beside it; the advert does not show that work being handled.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
Notes from the last meeting
The secretary checks dates, decisions and who needs to act.
A new cheaper helper
Its advert claims better results on a different set of tasks.
An urgent deadline
Missing one important date could matter more than smoother wording.
What would you do?
What should the secretary do before switching?
Replace the old helper because the score is higherWhy this choice?
The score may measure a different job. Try fresh examples of the club's actual notes, including difficult dates and urgent actions, before exposing everyone to a new mistake pattern.
Compare both helpers on fresh club-style examplesWhy this choice?
Keep the current process while checking important details, correction effort and time. Agree what would count as a failure and how to return to the old helper before trying the new one live.
What to take away
Judge a new helper on your actual work, including the rare details that would hurt to lose.
What if something changes?
Someone who did not tune the new helper checks fresh examples. It meets the club's agreed checks, including urgent dates. The secretary can try it on a small share of notes, review every draft and switch back immediately.
How much change does that evidence support?
Try a small share with review and a stop ruleWhy this choice?
That tests real use without changing everything at once. Stop if an important detail is missed, correct affected notes and compare total effort before the secretary approves wider use.
Move all drafts over, keeping the secretary's reviewWhy this choice?
Review still helps, but moving everything at once exposes all notes to mistakes the examples may have missed. Start small, check real correction effort and let the secretary decide whether wider use is worthwhile.
What to take away
Good local evidence can justify a limited trial, not the removal of every safeguard.
The idea behind this story
Increase use as relevant evidence grows, and keep a practical way to stop and correct mistakes.
Which rare mistake would make you stop using a new helper even if most notes looked better?
The technical connection: Evaluation-gated canary rollout
Independent task and slice evaluations qualify a candidate for limited traffic. Live monitoring and rollback bound exposure, while a release owner decides expansion and humans retain high-impact approvals.
Advanced: A better average score can hide a worse release
Evaluate a replacement model on the actual work, then release narrowly when independent evidence and rollback support it.
Model operations and release management · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A team considers replacing the model that drafts internal service summaries; cheaper calls would help, but dropped urgent details could mislead staff.
Your initial decision
Should the team replace the current model on the strength of a headline score?
The fictional candidate costs 25% less per call, but the advertised benchmark does not measure this team's summaries.
Rare urgent-service notes and less common language variants must remain accurate; an average score can hide these failures.
Staff review summaries before any high-impact action; the model cannot close urgent cases or change service priority.
No candidate-specific regression set, rollback rehearsal or operational owner is ready yet.
Compare the alternatives
Keep the baseline while building local release evidence
Holding the release delays potential savings, but preserves the known workflow while the team measures local quality, latency and review burden.
Plan a limited canary after local acceptance checks
A canary can expose real operational behavior with limited traffic, but without acceptance criteria or rollback it is not yet a controlled experiment.
Replace the model with staff reviewing every summary
A broad switch captures savings quickly while retaining human review, but exposes every reviewer to unmeasured errors and may erase the savings in corrections.
Mechanism, trade-offs, and evidence
Evaluate the complete workflow, including prompts, tools and reviewer correction, rather than assuming a model-only score transfers.
Hold out examples from candidate selection and inspect failure slices separately so a common easy case cannot hide a consequential regression.
A cheaper call is valuable only if the system still produces usable work; include latency, retries and review cost in the comparison.
Reconsider after a change
The team completes an independent comparison with predefined slice thresholds, rehearses rollback and assigns a release owner; the candidate now qualifies for a constrained production trial.
How much rollout does the new evidence justify?
An illustrative held-out set of 400 cases meets the team's predefined quality thresholds in each tested slice; 60 urgent cases contain no missed urgent detail.
Those finite results are not a safety guarantee; rare and untested situations remain possible.
The release owner approves a 5% canary with staff review, a known-baseline fallback and monitoring of corrections, latency and urgent-detail misses.
Any confirmed urgent-detail miss stops the canary; broader rollout requires owner review of live outcomes, not automatic promotion on traffic volume.
Compare the alternatives
Retain the baseline if live monitoring cannot be staffed
The established model remains a valid fallback and avoids unmanaged exposure, but holding without a concrete blocker delays testing the demonstrated potential savings.
Run the approved canary with explicit stop conditions
Limited live traffic tests end-to-end cost and reviewer impact while capping exposure, but requires rapid fallback and review of unexpected failure slices.
Move every team to the candidate after the offline pass
Full replacement would realize savings sooner, but skips the agreed live comparison and multiplies exposure to behavior absent from the finite test set.
Mechanism, trade-offs, and evidence
The recommendation changes because local evidence and operational readiness now exist, not simply because a newer model is available.
Monitor user-visible outcomes as well as provider availability: a fast successful request can still omit a detail that matters.
Rolling back the model prevents future candidate outputs but does not retract summaries already used; identify affected cases and arrange human correction.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
June volunteers at a local advice desk. Its usual online helper stops working. The desk still has approved information sheets and a staffed phone line. Another website works, but it is not approved to receive visitors' private questions.
The problem: The desk needs a useful backup, not an unnoticed transfer of private information to a new company.
Picture the situation: The quiet screen shows the interruption, the closed envelope represents a private question, and the leaflets and phone show other help.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
The usual helper is unavailable
Visitors are waiting, but the online service is not answering.
Some questions are private
A visitor has shared personal details with the desk.
Other help is still available
Information sheets and the staffed phone line remain open.
What would you do?
What should June offer while the service is down?
Explain the outage and offer sheets or staff helpWhy this choice?
Visitors get an honest next step without their information moving somewhere unexpected. Send urgent needs to staff and make clear which help is temporarily unavailable.
Paste the questions into the working websiteWhy this choice?
A working site is not automatically allowed to receive private information. Keep private questions within the desk's approved process and use local help until a suitable backup is approved.
What to take away
A backup should preserve people's trust and information boundaries, not just produce an answer.
What if something changes?
The desk owner approves and tries a backup service for public questions about opening times and directions only. Private questions still stay with staff. If the backup also fails, the sheets and phone line remain available.
How should June use the backup next time?
Send every question because the backup is approvedWhy this choice?
The approval covers public opening times and directions, not personal cases. If June is unsure whether a question contains private details, keep it with staff rather than stretching the permission.
Use it only for the approved public questionsWhy this choice?
That restores useful help within the agreed boundary. Keep private or uncertain requests with staff, and return to the sheets or phone line if the backup cannot answer.
What to take away
A tested, approved backup can help with a defined kind of work while other work keeps its safer route.
The idea behind this story
Choose a continuity plan that is both useful and permitted for the information involved.
Which questions could safely use a public backup, and which should stay with a person?
The technical connection: Permission-aware provider failover
Routing checks data class, recipient approval and tested quality before switching providers. Bounded attempts prevent repeated failures; uncertain external actions require reconciliation rather than blind replay.
Advanced: A backup provider must be allowed to receive the work
Maintain service during an outage without quietly moving private data or duplicating consequential actions.
Business continuity and provider outages · 9 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A service desk relies on an external model to draft responses; it needs an honest continuity plan when that provider stops answering.
Your initial decision
What should the service do when its only approved provider is unavailable?
In the fictional incident, the primary model has failed for 15 minutes and request queues are growing.
Only that provider is approved for private customer case text; another reachable provider has no authorization for these records.
Approved local response templates and staff handling remain available, including a route for urgent cases.
The draft service cannot execute customer actions; any separate action with an unknown result must be reconciled, not replayed.
Compare the alternatives
Queue requests for a bounded wait on the primary
A short bounded queue may bridge a brief interruption without changing processors, but prolonged waiting can hide urgency and increase abandonment.
Use local templates and a visible staff handoff
Degraded service offers less tailored help but preserves approved data boundaries and gives customers a clear route while the provider recovers.
Route drafts to the reachable secondary provider
A secondary could restore drafting speed, but current reachability does not establish authorization, data handling terms or quality for these cases.
Mechanism, trade-offs, and evidence
Continuity is a user-service problem, not a requirement to keep model calls flowing at any cost.
Availability and permission are independent: a reachable endpoint is not an approved destination for customer information.
Bound waits and expose degraded behavior; otherwise a technically orderly retry loop can leave customers without useful help.
Reconsider after a change
A continuity review approves a tested secondary for a defined non-sensitive request class; routing now separates that class from private cases and includes recovery limits.
What fallback should activate during the next primary outage?
An independent illustrative replay of 180 non-sensitive draft requests meets the agreed quality and latency thresholds on the secondary.
The data owner approves only the specified request class; private or uncertain classifications remain on local templates and staff handling.
Routing has a deadline, a single allowed fallback attempt and budget caps; health checks prevent repeated switching between providers.
The secondary produces drafts only; binding commitments still require authorized human approval and unknown action outcomes are never replayed.
Compare the alternatives
Hold every request until the primary recovers
Waiting avoids invoking the secondary, but needlessly delays the approved request class now that a tested and bounded continuity path exists.
Keep local service for private or uncertain requests
Templates and staff protect records outside the approval boundary, but offer less tailored help than the secondary for requests that do qualify.
Fail over only the approved non-sensitive draft class
A tested secondary restores useful drafting within the permitted boundary, while bounded attempts and local fallback limit cost and repeated failure.
Mechanism, trade-offs, and evidence
The changed permission boundary and independent task evidence together justify fallback; neither alone would have been sufficient.
Measure useful completed requests rather than successful HTTP calls, and retain a local mode if both providers fail.
Provider switching applies to permitted draft computation, not blind replay of actions that may already have affected a customer.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
A volunteer kitchen wants help writing shift handovers. A coordinator suggests an AI drafting tool. Volunteers already have a paper form, and some find new screens harder to use than others.
The problem: The team needs clearer handovers with less total effort, not a rule that everyone must use a new tool.
Picture the situation: The arriving shift needs a handover; the paper form and proposed laptop show the current approach and an idea not yet tried.
123
AI-illustrated teaching scene. Follow the arrows from 1 to 3; they show how to read the story, not actions taken by an AI.
A new shift arrives
Volunteers need to know what is ready and what still needs doing.
The current handover form
People already use a paper form to pass on important details.
A proposed drafting helper
The coordinator wonders whether it will make handovers easier for everyone.
What would you do?
How should the coordinator try the idea?
Ask everyone to use it at every shiftWhy this choice?
That could spread extra work before anyone checks the benefit. Start with willing volunteers from different shifts and keep the existing option, rather than judging people by how often they use the tool.
Offer a supported trial and compare complete handoversWhy this choice?
Count checking and correction time as well as typing saved. Invite different access needs, keep a comfortable way to decline and have people review notes before acting on them.
What to take away
Try the tool against real work, with a safe alternative. Using it more is not the same as being helped more.
What if something changes?
Volunteers say the helper writes quickly, but they spend longer correcting and copying its notes. The shifts use different headings, and one screen is difficult to navigate. A shared, accessible form could remove those problems without AI.
What should the coordinator do next?
Fix the shared form and remove repeated copyingWhy this choice?
That addresses the work people actually struggle with. Include all shifts and access needs, then compare the helper with the better form later; nobody should be blamed for reporting problems or choosing paper.
Require more training before people can declineWhy this choice?
Training will not fix mismatched headings or repeated copying. Listen to the observed problems and improve how handovers work first, while keeping feedback separate from judgments about volunteers.
What to take away
When a trial reveals a simpler fix, use it. Do not turn a tool problem into a people problem.
The idea behind this story
Measure the whole job and change the process when that helps people more than expanding the tool.
What would you count besides typing time to know whether this helper really helps?
The technical connection: Outcome-based adoption
Measure task quality, total effort and accessibility against a baseline. Nonpunitive feedback guides rollout; tool-use counts must not become employee performance or employment decisions.
Advanced: A busy assistant is not an adopted improvement
Measure whether a team tool helps real work, then change course when corrections and duplicate entry outweigh the benefit.
Team change management and organizational adoption · 8 minutes
The problem
Synthetic practice scenario: all quantities and evaluation outcomes are illustrative, not reported research. Fictional outcomes are not guarantees. A team lead considers an AI handover helper for shift notes; the goal is fewer missed handoffs and less effort, not more tool usage or employee surveillance.
Your initial decision
How should the team learn whether a handover helper is worth adopting?
The fictional team has 16 staff across shifts and an existing handover template with a known completion-time baseline.
Volunteers can trial drafts with a manual alternative; staff review handovers before consequential operational action.
Feedback must include different shifts and access needs, not only confident early adopters.
Usage and feedback are for workflow improvement, not individual performance scoring, discipline or employment decisions.
Compare the alternatives
Improve the existing handover template first
A clearer template may solve missing information at low cost, but the team has not yet established whether writing effort or template structure is the main obstacle.
Launch across shifts with training and usage targets
A common launch offers shared support and consistent tooling, but participation targets can mask correction burden before the team knows whether the helper helps.
Run a supported volunteer pilot against the baseline
A small trial measures total handover work and missed details with staff feedback, but needs coverage across shifts and cannot represent everyone automatically.
Mechanism, trade-offs, and evidence
Define success as useful completed handovers, including review and correction time, rather than drafts generated or sessions opened.
Invite different working conditions into the trial and provide support so a usability obstacle is not mistaken for resistance to change.
Keep employee evaluation out of the experiment; honest feedback becomes less likely if trying or rejecting the tool affects employment judgments.
Reconsider after a change
The pilot saves typing but adds correction and duplicate-entry work; observations show the deeper issue is inconsistent handover fields between shifts, not lack of drafting skill.
What should the team change before asking more colleagues to adopt the helper?
An illustrative independent work sample shows 4 minutes saved typing but 6 extra minutes correcting and copying each handover: a net increase of 2 minutes.
Night-shift staff identify missing ownership fields and a screen-reader obstacle that the initial volunteer group did not reveal.
The team can agree a shared handover form and remove duplicate entry without using a model.
Staff feedback remains nonpunitive; no one is labeled uncooperative or evaluated for choosing the manual route.
Compare the alternatives
Fix shared fields and duplicate entry before expansion
A workflow repair postpones wider AI use while addressing measured overhead and accessibility gaps that more generated drafts would not solve.
Expand the launch with more drafting training
Extra training can help people use a tool, but it cannot remove duplicate systems or missing handover ownership and may spread the observed extra work.
Keep a small optional pilot for unresolved drafting tasks
A narrowly focused trial could answer remaining questions, but needs a distinct task and must not distract from the shared workflow repair.
Mechanism, trade-offs, and evidence
Count all the work: saving typing while adding more correction is a loss here, not a successful pilot with an adoption problem.
The new evidence points to process and accessibility changes; simplifying is a positive outcome when it improves real work.
After fixing the baseline, reassess specific drafting needs with representative staff rather than preserving the original tool decision for its own sake.
Related technical concepts
Follow-up lessons retain their existing sign-in and plan requirements.
Learning together? Pick a story, compare your choices, and talk about what might change your mind. There are no verified team scores or completion records here.
Self-checks and completion records help you reflect; they are not independently verified credentials. Credential availability, assessment, and eligibility are separate.